Author: admin

  • Why Your Phone Battery Degrades — and How to Slow It

    Why Your Phone Battery Degrades — and How to Slow It

    Why Your Phone Battery Degrades — and How to Slow It

    You’ve probably noticed it before: your phone used to last a full day with ease, but now you’re reaching for a charger by mid-afternoon. That creeping decline isn’t your imagination. Every lithium-ion battery inside a modern smartphone is a consumable component, designed to wear out over time. The good news is that while some degradation is inevitable, you can dramatically slow the process by understanding the chemistry and adjusting a few everyday habits. In this article, we’ll explore exactly why your phone battery degrades, the science behind the fade, and practical, research-backed strategies to extend its lifespan.

    The Science of Lithium-Ion Batteries

    To understand why batteries degrade, it helps to know how they work in the first place. Nearly all modern smartphones use lithium-ion batteries, which rely on the movement of lithium ions between two electrodes: the positive cathode and the negative anode. During discharge, lithium ions travel from the anode to the cathode through an electrolyte, releasing energy in the process. When you charge the phone, an external voltage pushes those ions back to the anode, storing energy for later use.

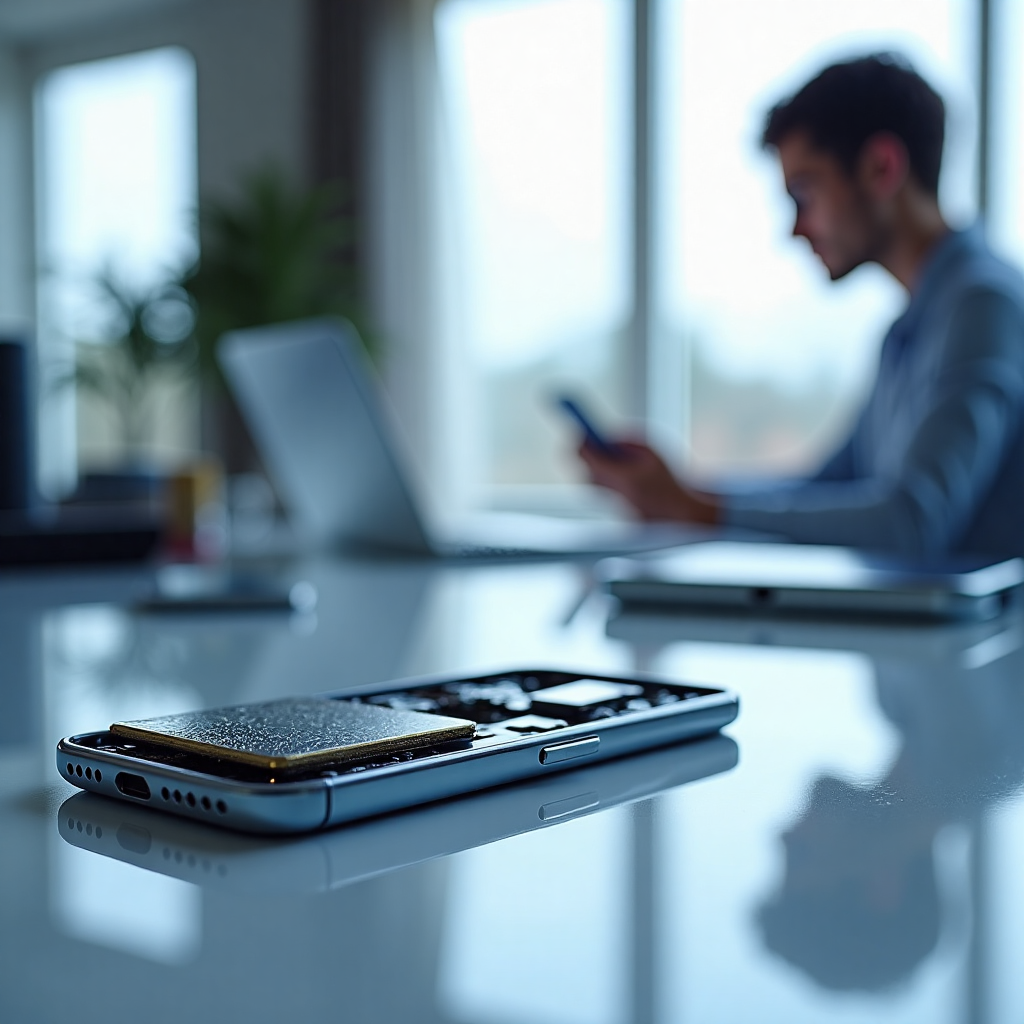
    This process is elegant, but it isn’t perfectly reversible. Each time lithium ions shuttle back and forth, tiny side reactions occur. Some lithium atoms become trapped in the electrode structure, reducing the number of free ions available for future cycles. The electrolyte slowly breaks down, forming solid deposits on the electrodes. Over time, these changes reduce the battery’s capacity — the total amount of charge it can hold — and increase its internal resistance, meaning the battery has to work harder to deliver the same amount of power. That’s why an older phone not only drains faster but may also shut down unexpectedly under heavy load.

    Charge Cycles and Depth of Discharge

    A charge cycle is defined as using 100% of a battery’s capacity, but not necessarily all at once. For example, using 50% today and 50% tomorrow counts as one full cycle. Most smartphone batteries are rated for 300 to 500 full cycles before their capacity drops to about 80% of the original. However, the depth of discharge — how much of the battery you use before recharging — plays a huge role in how quickly those cycles add up. Draining your battery from 100% to 0% puts significantly more stress on the cell than cycling between 40% and 80%. Shallow discharges are gentler because the electrodes remain in a more stable voltage range, reducing the mechanical and chemical strain.

    Heat: The Silent Killer

    Heat is among the most destructive forces for lithium-ion batteries. High temperatures accelerate every chemical reaction inside the cell, including the unwanted side reactions that cause degradation. According to battery research, a battery stored or operated at 40°C (104°F) can lose up to 35% of its capacity in a single year, compared to only about 20% at 25°C (77°F) and under 10% at 20°C (68°F). Heat also increases the risk of electrolyte decomposition and can cause the battery to swell, which is both a performance and safety hazard. The heat can come from external sources — like leaving your phone in a hot car — or from internal sources, such as fast charging or intense gaming while plugged in.

    High Voltage and Overcharging Stress

    Lithium-ion batteries are happiest in a moderate voltage range, roughly between 3.7 and 4.2 volts per cell. When a battery is charged to its maximum voltage, the positive electrode becomes highly oxidizing, and the negative electrode becomes highly reducing. This stressed state promotes the breakdown of the electrolyte and accelerates the loss of lithium inventory. Even after the charger is disconnected, a battery kept at 100% charge remains in that high-voltage state, slowly aging. That’s why smartphones have built-in charge controllers that stop the current at 100%, but the battery is still held at maximum voltage, which is not ideal for long-term health. Similarly, letting a battery sit at very low charge for extended periods can push it into deep discharge, where the voltage drops too low and irreversible damage to the electrode structure can occur.

    Fast Charging: Convenience vs. Longevity

    Fast charging is a modern convenience that many of us rely on, but it comes with a trade-off. To pump more energy into the battery in a short time, fast chargers increase both the current and the voltage. This influx of power generates additional heat and increases the stress on the battery’s internal components. While modern fast-charging protocols are designed to manage temperature and taper the current as the battery fills, frequent use of high-wattage chargers still accelerates degradation compared to slower, standard charging. The effect is modest on a single charge, but over hundreds of cycles, the cumulative impact can shorten the battery’s lifespan by several months or more.

    Age and Calendar Aging

    Even if you never used your phone, the battery would still degrade. This phenomenon is called calendar aging, and it’s driven by the chemical instability of the materials inside the cell. A lithium-ion battery stored at room temperature can lose about 2–3% of its capacity per year simply due to time. The rate of calendar aging increases with temperature and with the state of charge. A battery stored at 100% charge in a warm room will age much faster than one stored at 50% charge in a cool environment. This is why phone manufacturers often ship new devices with batteries charged to around 50% — it’s the optimal storage voltage for minimizing calendar aging.

    How to Slow Battery Degradation

    Now that you understand the main culprits, let’s translate that knowledge into action. The following strategies are simple, practical, and effective at extending the usable life of your smartphone battery. None of them require special tools or significant lifestyle changes — just a bit of mindfulness.

    Adopt the 20–80% Charging Habit

    The single most impactful habit you can develop is to keep your battery between 20% and 80% charge as much as possible. This range avoids the two most stressful states: very low voltage (below 20%) and very high voltage (above 80%). Charging to 100% every night is convenient, but it holds the battery at maximum voltage for hours, accelerating degradation. Similarly, regularly letting the battery drain below 20% forces the cell to operate near its lower voltage limit, where internal resistance rises and the anode can be damaged. You don’t need to be obsessive about it — an occasional full charge or deep discharge is fine — but making 20–80% your default routine can add hundreds of cycles to your battery’s life.

    Avoid Extreme Temperatures

    Keep your phone out of hot cars, direct sunlight, and warm pockets for extended periods. If you’re outside on a hot day, try to keep the device in the shade and avoid using it heavily while it’s already warm. Cold temperatures are less damaging in the short term but can cause temporary capacity loss and, in extreme cases, permanent damage if the battery is charged while below freezing. The ideal operating temperature for a lithium-ion battery is between 20°C and 25°C (68°F to 77°F). If your phone feels uncomfortably warm to the touch, take a break from charging and remove any case that might be trapping heat.

    Use Optimized Battery Charging Features

    Most modern smartphones include software features designed to protect the battery. On iPhones, Optimized Battery Charging learns your daily routine and waits to finish charging past 80% until you actually need it, reducing the time the battery sits at full charge. On Android devices, similar features like Adaptive Charging or Battery Care can limit charging to 80% or pause charging overnight. Enable these features in your settings. They are perhaps the easiest way to slow degradation without changing your habits, because the phone does the work for you.

    Choose the Right Charger and Cable

    Always use a charger and cable from a reputable manufacturer, ideally the one that came with your phone or a certified third-party accessory. Cheap, uncertified chargers may deliver unstable voltage or excessive current, which can overheat the battery and cause rapid degradation. If your phone supports fast charging but you don’t need it, consider using a standard 5W or 10W charger for overnight charging. Slower charging generates less heat and is gentler on the battery, making it a wise choice for the long haul.

    Reduce Fast Charging When You Can

    Fast charging is incredibly useful when you’re in a hurry, but it shouldn’t be your default method. If you have time, use a regular charger. Reserve high-wattage fast charging for emergencies or when you genuinely need a quick top-up. Also, avoid using your phone for gaming or video streaming while it’s fast charging, because the combined heat from the charger and the processor can push temperatures into the danger zone. If you must use the phone, unplug it first or switch to a slower charger to reduce thermal stress.

    Update Software and Monitor Battery Health

    Phone manufacturers regularly release software updates that include battery management improvements. These updates can optimize how the phone charges, adjust background activity, and even repair minor battery calibration issues. Keeping your operating system up to date ensures you benefit from the latest battery-saving algorithms. Additionally, both iOS and Android now include battery health tools that show your current maximum capacity and peak performance capability. Check this periodically. If your battery health drops below 80%, you may notice reduced runtime and performance throttling, which is a sign that a replacement is on the horizon.

    Common Myths About Phone Battery Care

    There’s a lot of outdated advice floating around about batteries, much of it rooted in older nickel-based battery technology. Let’s clear up a few persistent myths.

    Myth: You Should Fully Drain Your Battery Before Charging

    This advice applied to nickel-cadmium and nickel-metal hydride batteries, which suffered from a “memory effect” if not fully discharged regularly. Lithium-ion batteries have no memory effect. In fact, fully draining a lithium-ion battery is harmful and should be avoided. The best practice is to charge before you hit 20%.

    Myth: Closing Background Apps Saves Battery Health

    Swiping away apps in the app switcher does not improve battery life or health. In fact, force-closing and reopening apps can use more energy than simply leaving them suspended in memory, because the phone has to reload the entire app from scratch. The operating system is already optimized to manage background tasks efficiently. If you want to reduce battery drain, focus on disabling unnecessary location services, push notifications, and background refresh for apps you don’t use.

    Myth: Overnight Charging Will Destroy Your Battery

    Modern smartphones are smart enough to stop charging at 100%, so leaving your phone plugged in overnight is not inherently dangerous. However, holding the battery at 100% for several hours does accelerate calendar aging, which is why optimized charging features are so valuable. If your phone supports overnight charging optimization, use it. If not, consider charging to 80% before bed and topping up in the morning, or use a smart plug that cuts power after a set time.

    When to Replace Your Battery

    Even with the best care, every lithium-ion battery will eventually need replacement. A good rule of thumb is to consider a new battery when the health drops below 80% of its original capacity. At that point, you’ll likely notice shorter runtimes, unexpected shutdowns under load, and possibly a swollen back cover. Battery replacement is a relatively inexpensive service compared to buying a new phone, and it can add years to the life of an otherwise perfectly functional device. Many manufacturers offer official battery replacement programs, and third-party repair shops can also do the job, though it’s wise to insist on high-quality, certified batteries.

    Conclusion

    Your phone battery is a marvel of modern chemistry, but it’s not immortal. The degradation you experience is the result of predictable chemical processes accelerated by heat, high voltage, deep discharges, and time. By understanding these factors, you can make small adjustments that yield big dividends: keep your charge between 20% and 80%, avoid heat, use optimized charging features, and be mindful of fast charging. None of this requires perfection — just consistency. With a little care, you can keep your phone running longer on a single charge and delay the inevitable battery replacement by a year or more. In a world where we rely on our phones for nearly everything, that extra lifespan is well worth the effort.
  • The Truth About “Unlimited” Data Plans: What Carriers Don’t Tell You

    The Truth About “Unlimited” Data Plans: What Carriers Don’t Tell You

    Walk into any carrier store, browse a mobile provider’s website, or watch a prime-time commercial, and you will be hit with the same promise: unlimited data. It sounds liberating. No more counting megabytes, no more mid-month warnings, no more overage fees. For millions of smartphone users, an unlimited plan feels like the obvious choice. But after ten years of covering the wireless industry, I can tell you that “unlimited” rarely means what you think it means. Behind the marketing glow lies a web of fine print, network management policies, speed caps, video throttling, and hotspot restrictions that quietly shape your real-world experience.

    In this article, we are going to unpack the truth about unlimited data plans. We will look at how carriers define “unlimited,” why your speeds can slow to a crawl even when you haven’t technically hit a data cap, and what you need to know before signing up for the shiniest plan on the shelf. By the end, you will understand that unlimited data is not a lie, but it is also not the whole story.

    What “Unlimited” Actually Means in the Wireless Industry

    The first thing to understand is that “unlimited” is a marketing term, not a technical promise. In the early days of smartphones, carriers offered limited data buckets—2GB, 5GB, 10GB—and charged overage fees when you exceeded them. Then came the era of unlimited plans, designed to eliminate anxiety and attract customers. However, wireless spectrum is finite. A cell tower can handle only so much traffic at once. If every customer used truly unlimited high-speed data all month long, networks would collapse. So carriers solved the problem by redefining what “unlimited” means.

    In practice, an unlimited plan means you can use as much data as you want without being cut off or charged extra. But it does not mean you get unlimited premium high-speed data. Most plans include a set amount of “priority” or “premium” data—such as 50GB or 100GB per month. After you cross that threshold, your speeds can be slowed temporarily when the network is congested. This is called deprioritization, and it is the most misunderstood part of unlimited plans.

    The Fine Print You Probably Missed

    Before you choose an unlimited plan, you need to read the fine print. Carriers are legally required to disclose network management practices, but the language is often buried in footnotes or hidden behind expandable tabs. Here are the most common restrictions that apply to “unlimited” plans:

    • Premium data thresholds: After using a specific amount of high-speed data—often 50GB, 100GB, or more—your connection may be temporarily slowed during busy times.
    • Video streaming caps: Many unlimited plans stream video at standard definition by default, usually around 480p or 720p, unless you pay extra for a higher-tier plan.
    • Mobile hotspot limits: Your phone data may be unlimited, but the amount you can share to other devices through a hotspot is often capped, such as 10GB or 25GB of high-speed hotspot data.
    • International roaming restrictions: “Unlimited” usually applies only to domestic use. International data may be limited to 2G speeds or require an add-on.
    • Always-on deprioritization: Some budget unlimited plans are always subject to slower speeds than premium plans, even before you hit a data threshold.

    These restrictions are not necessarily deceptive, but they are easy to overlook if you only pay attention to the word “unlimited.” The key is to understand how each policy affects your daily habits.

    Deprioritization vs. Throttling: Understanding the Difference

    One of the most important distinctions in the unlimited data conversation is the difference between deprioritization and throttling. They are often confused, but they work differently.

    What Is Throttling?

    Throttling is a hard speed limit. For example, a carrier may slow your data to 128Kbps—fast enough for basic email but painful for video or web browsing—for a specific reason, such as after you exceed a hotspot allowance or while roaming internationally. Once throttled, your speed stays reduced regardless of whether the network is busy.

    What Is Deprioritization?

    Deprioritization does not automatically reduce your speed. Instead, it places your traffic behind other users when the network is congested. If you are in a crowded stadium or downtown area at peak hours, you may notice slower speeds than someone who has not exceeded their premium data limit. But if the network is not congested, you may see no slowdown at all. This practice allows carriers to manage limited capacity while still offering “unlimited” data.

    The real-world impact varies by location, time of day, and carrier. A user in a rural area may never notice deprioritization, while someone in a major city may feel it every evening. This is why two people on the same unlimited plan can have completely different experiences.

    Video Streaming: The Hidden Speed Bump

    Video streaming is one of the most data-hungry activities on a smartphone. A single hour of high-definition video can use 3GB or more. To protect their networks, carriers often limit video streaming quality on unlimited plans. This is often called video optimization or a “DVD-quality” cap.

    For example, a standard unlimited plan may stream video at 480p on a phone, while a premium plan may allow 720p or 4K. The difference is noticeable, especially on larger screens. If you watch a lot of YouTube, Netflix, or TikTok, you might find that your “unlimited” plan delivers softer images than you expected. Carriers usually allow you to purchase an add-on or upgrade to a higher-tier plan to remove the cap, but that costs extra.

    Many users never realize they are being capped because video services automatically adjust quality based on available bandwidth. Your phone’s screen is small enough that 480p can look acceptable, but the moment you cast to a TV or use a tablet, the difference becomes obvious.

    Mobile Hotspot: The Unlimited Loophole

    Mobile hotspot is another area where “unlimited” quietly becomes limited. When you use your phone as a Wi-Fi hotspot, you are sharing your cellular connection with a laptop, tablet, or other device. Hotspot data is often treated separately from on-phone data. Even if your plan includes unlimited smartphone data, the hotspot allowance may be capped at a set amount of high-speed data—such as 15GB, 40GB, or 60GB—depending on the plan.

    After you exceed the hotspot cap, the hotspot may be slowed to a crawl, often around 600Kbps or lower. That is barely enough for basic web browsing and email. Video calls, large file downloads, and streaming become nearly impossible. If you rely on a hotspot for remote work, travel, or as a backup internet connection, this limitation can be a rude awakening.

    International Roaming: Unlimited Has Borders

    Another common misconception is that an unlimited plan covers international travel. In reality, most unlimited plans apply only to domestic use within the United States. Some carriers include limited international data in Canada and Mexico, but the terms vary. Even when international roaming is included, speeds are often reduced to 2G or 3G levels, making maps and messaging barely usable.

    If you travel frequently, you will likely need an international add-on, a local SIM card, or a travel eSIM. Otherwise, your “unlimited” plan will not save you from the frustration of unusably slow data abroad. Always check the roaming policy before you depart, because roaming charges can be expensive if you use data outside covered countries.

    Network Priority: Not All Unlimited Plans Are Equal

    Carriers often sell multiple tiers of unlimited plans. The base plan may be cheaper, but it comes with lower network priority. This means that during congestion, customers on premium plans get faster speeds than those on entry-level plans. Even if you have not exceeded any data threshold, you may still experience slower speeds simply because you are on a lower-tier plan.

    For example, a carrier might offer a basic unlimited plan that is always subject to deprioritization, a mid-tier plan with 50GB of premium data, and a top-tier plan with truly unlimited premium data and 4K video. The differences can be significant. If you are a heavy data user, choosing the cheapest unlimited plan may lead to frustration during peak hours. Understanding network priority can help you pick the right plan for your needs.

    The Cost of “Unlimited”

    Unlimited plans are rarely the cheapest option. Carriers aggressively advertise low starting prices, but those prices often require multiple lines, autopay discounts, or trade-ins. A single line on a premium unlimited plan can easily cost $80 to $100 per month or more. Add-ons for high-definition video, international roaming, or extra hotspot data increase the cost further.

    This does not mean unlimited plans are a bad value. For many families and heavy data users, they are the most convenient choice. But it is important to compare the total cost, not just the headline price. If you only use 4GB of data per month, an unlimited plan may be overkill. A cheaper limited plan or a prepaid option could save you hundreds of dollars per year.

    Who Should Choose an Unlimited Plan?

    Unlimited plans make the most sense for specific types of users. If you fall into one of the following categories, an unlimited plan may be right for you:

    • Heavy streamers: If you watch hours of video on cellular data every month, an unlimited plan prevents overage fees and gives you peace of mind.
    • Remote workers and travelers: People who rely on cellular data for work, video calls, and cloud apps often benefit from unlimited data, especially if they need hotspot access.
    • Large families: With multiple lines, unlimited plans can be cost-effective and easier to manage than tracking individual data buckets.
    • Anyone who hates data anxiety: If the thought of running out of data stresses you out, unlimited plans remove that worry.

    On the other hand, if you are usually connected to Wi-Fi at home and work, use less than 5GB of data per month, or want the lowest possible bill, a limited or prepaid plan may serve you better.

    How to Read the Fine Print Like a Pro

    After years of writing about wireless plans, I have developed a simple checklist for evaluating any unlimited plan. Before you sign up, ask these questions:

    • How much premium data is included before deprioritization may occur?
    • What is the video streaming quality on the plan? Can it be upgraded, and at what cost?
    • How much mobile hotspot data is included at high speed?
    • What happens after the hotspot allowance is used? Is the hotspot throttled to a specific speed?
    • Does the plan include international roaming? Which countries are covered, and at what speeds?
    • Is the plan always subject to deprioritization, or does it include a set amount of priority data?
    • Are there taxes and fees included in the advertised price, or are they extra?
    • What is the multi-line discount structure? Does the advertised price require autopay or paperless billing?

    Answering these questions will give you a much clearer picture of what you are actually buying. The goal is not to avoid unlimited plans altogether, but to choose one that matches your needs without paying for benefits you will never use.

    The Future of Unlimited Data

    The definition of “unlimited” continues to evolve. As 5G networks expand and carriers invest in more spectrum, capacity increases. This has allowed some carriers to offer more generous premium data thresholds and even truly unlimited high-speed data on top-tier plans. However, the same economic realities remain: spectrum is finite, demand keeps growing, and video streaming consumes ever more bandwidth.

    In the coming years, we are likely to see more granular network management, including plans optimized for specific types of content, AI-driven traffic shaping, and new pricing models. The word “unlimited” will probably never return to its dictionary definition—unrestricted in every way—because wireless networks cannot support that for everyone at once. Instead, carriers will keep refining the balance between marketing appeal and network reality.

    The Bottom Line

    The truth about unlimited data plans is that they are a trade-off, not a trick. You can use as much data as you want without overage fees, but you may face slower speeds, lower video quality, and limited hotspot access depending on your plan and your location. For most people, these limitations are manageable. For heavy users, the right premium plan can deliver an excellent experience. The key is to understand the fine print and choose a plan based on your actual usage, not just the word “unlimited.”

    Wireless carriers are not lying when they advertise unlimited data. They are just using a definition that fits the realities of network engineering. As a consumer, your job is to read between the lines, ask the right questions, and make an informed decision. Unlimited data can be a great value—but only if you know what you are really getting.

  • Automation and Digital Transformation: Reclaiming Productivity by Tackling Tech Debt

    Automation and Digital Transformation: Reclaiming Productivity by Tackling Tech Debt

    Digital transformation is no longer a buzzword reserved for tech giants. Organizations across every sector are investing in automation, cloud migration, artificial intelligence, and data-driven decision-making. The promise is compelling: faster operations, fewer manual errors, and the ability to scale without proportionally increasing headcount. Yet many transformation initiatives stall or fail to deliver expected returns. The culprit is often hidden in the codebase, infrastructure, and processes that have accumulated over years of rapid change: technical debt.

    Technical debt—the implied cost of future rework caused by choosing an expedient solution today—acts as a silent tax on productivity. It slows down developers, complicates integrations, and makes automation efforts brittle. When digital transformation layers new tools on top of an aging foundation, the organization may initially see gains, but those gains quickly erode. To truly unlock productivity through automation, leaders must confront tech debt head-on. This article explores the relationship between automation, productivity, digital transformation, and tech debt, and offers a practical framework for balancing innovation with long-term stability.

    Understanding Technical Debt in the Digital Age

    Technical debt is a metaphor introduced by software engineer Ward Cunningham. It describes the consequences of prioritizing speed over architectural quality. Just like financial debt, technical debt accrues interest. Every quick fix, skipped test, undocumented API, or duplicated module makes future changes more difficult and more expensive. Over time, the interest payments manifest as slower delivery cycles, increased defect rates, and rising frustration among engineering teams.

    In the context of digital transformation, tech debt is particularly dangerous. Transformation initiatives typically involve integrating legacy systems with modern platforms, migrating data to the cloud, and exposing services through APIs. If the underlying systems are riddled with debt, each new connection becomes a potential point of failure. Automation scripts break when data formats shift. Chatbots and AI models underperform because they rely on inconsistent data sources. The result is a transformation that looks impressive in slide decks but fails to deliver measurable business outcomes.

    Common Sources of Technical Debt

    Technical debt rarely appears overnight. It accumulates through a combination of business pressures, architectural compromises, and lack of governance. Common sources include:

    • Rushed deadlines: When teams are pushed to release features quickly, they may bypass refactoring or testing.
    • Legacy platforms: Older systems often lack modern interfaces, forcing workarounds that create brittle integration points.
    • Poor documentation: Undocumented code and infrastructure make it difficult to understand dependencies and safely modify systems.
    • Inconsistent standards: Without clear coding and architecture standards, different teams create divergent patterns that are hard to automate.
    • Deferred maintenance: Postponing upgrades, security patches, and dependency updates leads to compounding risk.

    How Automation Drives Productivity and Transformation

    Automation is one of the most effective ways to improve productivity. By removing repetitive manual tasks, organizations can free up human talent for higher-value work. In a digital transformation context, automation spans a wide spectrum: from simple workflow triggers to intelligent process automation using machine learning. The key is to automate the right processes—those that are frequent, rule-based, and stable enough to benefit from standardization.

    When automation is done well, it produces compounding benefits. Errors decrease because machines follow rules consistently. Cycle times shorten because tasks execute in parallel or around the clock. Employees experience less tedious work, which can improve morale and reduce turnover. Data quality improves because automated systems can validate and normalize information as it flows between systems. These gains create a foundation for more ambitious transformation efforts, such as predictive analytics and autonomous operations.

    Selecting High-Impact Automation Opportunities

    Not every process should be automated. A common mistake is to automate a broken process, which simply makes the failure happen faster. Instead, organizations should evaluate processes based on volume, variability, and value. The best candidates for automation often share these characteristics:

    • High frequency: The task is performed many times per day or week.
    • Clear rules: The input, logic, and output can be defined precisely.
    • Low exception rate: The process has few unexpected variations or edge cases.
    • Integration points: The process moves data between systems that already have APIs or connectors.
    • Material impact: Automating the task saves measurable time, reduces errors, or improves customer experience.

    By focusing on these criteria, teams can avoid automating unstable or ambiguous workflows that would create new forms of technical debt. It is also essential to involve the people who perform the process in the design of the automation. They understand the nuances and exceptions that documentation often misses.

    The Vicious Cycle: Tech Debt vs. Productivity Gains

    Many organizations invest heavily in automation expecting a productivity leap, only to find that gains flatten or reverse after initial success. This happens because automation often exposes the weaknesses of the underlying technical estate. If data is messy, automated reports produce wrong answers. If legacy systems have no APIs, automation relies on fragile screen scraping or manual file dumps. Each workaround adds another layer of complexity, which becomes its own tech debt.

    This creates a vicious cycle. Teams spend more time maintaining automation scripts than they did performing the original manual work. The automation layer becomes a fragile patchwork of scripts, scheduled jobs, and third-party connectors. When something breaks—a login page changes, a database schema shifts, or an API version is deprecated—the automation fails silently or throws errors that require manual intervention. The productivity gain evaporates, and the organization may conclude that automation “doesn’t work.” In reality, the problem is not automation but the accumulation of tech debt beneath it.

    The Compounding Interest of Legacy Decisions

    Technical debt behaves like compound interest, but in reverse: the longer you wait, the more it costs. A small shortcut taken today might save a few hours. But if that shortcut is in a core system used by dozens of downstream processes, each future change must account for the shortcut. Over a few years, the original savings can turn into thousands of hours of additional effort. This is especially true in digital transformation, where new systems are often built alongside old ones, creating a hybrid estate that is harder to manage than either alone.

    For example, a company might choose to keep a legacy order management system because replacing it is expensive. They build an API wrapper to expose order data to a new e-commerce frontend. The wrapper works, but it contains hard-coded assumptions about the legacy system’s data format. Months later, the legacy system receives a minor update that changes a field name. The API breaks, causing order failures. The team spends days debugging, and the automation that depended on the API also fails. This is a classic case of tech debt multiplying across layers.

    A Blueprint for Balancing Automation, Transformation, and Tech Debt

    Organizations do not have to choose between innovation and stability. The most successful digital transformation efforts treat tech debt reduction as a continuous discipline, not a one-time cleanup project. By following a structured approach, leaders can scale automation while gradually retiring the debt that threatens long-term productivity.

    1. Conduct a Systematic Tech Debt Audit

    You cannot manage what you cannot see. A tech debt audit involves mapping the current state of applications, infrastructure, data flows, and automation scripts. Each component should be assessed for age, maintainability, dependencies, and risk. Tools such as code quality scanners, dependency analyzers, and architecture fitness functions can provide objective data. The audit should also capture the human perspective: which systems do engineers fear touching? Which processes require constant manual fixes? This qualitative input is often the clearest signal of hidden debt.

    2. Prioritize Based on Business Impact

    Not all tech debt is equal. Some debt sits in rarely used modules, while other debt affects core customer journeys. Prioritize remediation based on the impact on revenue, customer experience, compliance, and operational risk. A simple matrix can help: high impact and high likelihood of failure should be addressed first. Low impact, low likelihood debt might be tolerated indefinitely, but should be documented and reviewed periodically.

    3. Embed Quality Gates into Automation Pipelines

    Prevention is better than cure. To stop new tech debt from accumulating, integrate quality checks into the software delivery pipeline. Automated tests, code reviews, static analysis, and architecture checks can run on every change. This ensures that automation scripts and application code meet minimum standards before they reach production. It also reduces the temptation to ship quick fixes under pressure, because the quality gate makes risky changes visible immediately.

    4. Allocate Dedicated Capacity for Modernization

    One of the most common reasons tech debt accumulates is that teams are never given time to fix it. Every sprint is filled with new feature requests, leaving no room for refactoring or dependency upgrades. Leaders should allocate a fixed percentage of engineering capacity—commonly 15 to 20 percent—to technical debt reduction and modernization. This may feel like a loss of velocity, but it is an investment that pays off in faster delivery later.

    5. Measure What Matters

    To sustain progress, track metrics that reflect both productivity and debt. Delivery lead time, change failure rate, mean time to recover, and the number of open high-risk defects are useful indicators. Automation utilization and error rates should also be monitored. These metrics create a feedback loop that shows whether automation is genuinely improving productivity or merely shifting work to maintenance tasks. Regularly review the data with leadership to maintain alignment and funding.

    Real-World Lessons from Digital Transformation Journeys

    Consider a mid-sized financial services firm that decided to automate its client onboarding process. The goal was to reduce manual data entry and speed up approvals. The initial automation used robotic process automation (RPA) to transfer data between a web portal and a legacy customer database. It worked for a few weeks, but then the portal changed its interface. The RPA bots broke, and the team had to rewrite dozens of scripts. The firm realized it had automated a fragile manual process without addressing the underlying integration problem.

    The solution was to redesign the onboarding workflow around a modern API layer. The firm built a customer data platform that provided a stable interface for both the portal and the legacy database. They then automated the new process using workflows that called APIs instead of scraping screens. The result was a 40 percent reduction in onboarding time and a significant drop in bot maintenance. By addressing the tech debt in the integration layer, the firm unlocked the full productivity benefits of automation.

    Another example comes from a healthcare provider that wanted to use machine learning to predict patient no-shows. The data science team spent months cleaning data from multiple scheduling systems. Each system had different formats, duplicate records, and missing fields. The team discovered that the majority of their time was spent on data wrangling, not model building. They paused the ML project and invested in a data quality initiative. By standardizing patient identifiers and scheduling data, they reduced preparation time by 60 percent. The predictive model then delivered accurate results because it was built on a reliable data foundation.

    The Future of Automation and Digital Transformation

    The next wave of automation will be driven by artificial intelligence and hyperautomation. AI-powered tools can analyze unstructured data, make recommendations, and even write code. But these advanced technologies amplify the importance of clean, well-structured systems. An AI assistant that works on top of a messy codebase will produce unreliable results. Conversely, an organization with low tech debt can use AI to accelerate development, optimize operations, and deliver personalized customer experiences at scale.

    Digital transformation is not a destination; it is a continuous journey. As organizations adopt cloud-native architectures, microservices, and AI, they must also evolve their governance and engineering practices. The most successful organizations will be those that treat technical debt as a first-class citizen in their transformation strategy. They will automate not only business processes but also the detection and remediation of debt itself. This includes automated code refactoring, self-healing infrastructure, and AI-driven anomaly detection in applications.

    Productivity will increasingly be measured not by hours saved but by the ability to innovate quickly. When tech debt is under control, teams can experiment, learn, and pivot without being held back by fragile systems. Automation becomes a reliable force multiplier, and digital transformation delivers on its promise of agility and growth.

    Conclusion

    Automation and digital transformation hold immense potential to boost productivity and drive business growth. But that potential is often undermined by technical debt—the accumulated shortcuts, legacy dependencies, and undocumented workarounds that make modern systems brittle. Ignoring tech debt while pursuing aggressive automation is like building a skyscraper on a cracked foundation. The first few floors may go up quickly, but the building will eventually become unsafe and costly to maintain.

    The path forward requires a shift in mindset. Leaders must recognize that addressing tech debt is not an obstacle to transformation; it is a prerequisite. By conducting systematic audits, prioritizing high-impact improvements, embedding quality gates, allocating dedicated capacity, and measuring outcomes, organizations can create a virtuous cycle. Automation reduces manual labor, which frees up capacity to modernize systems, which in turn makes automation more reliable and productive.

    In the end, the companies that succeed in the digital age will not be the ones that simply adopt the latest tools. They will be the ones that build strong technical foundations, manage debt wisely, and use automation to amplify human creativity and value. By doing so, they will turn digital transformation from a risky gamble into a sustainable competitive advantage.

  • Designed to Last: How User Experience, Backward Compatibility, Firmware Updates, and Repairability Can Combat E-Waste

    Designed to Last: How User Experience, Backward Compatibility, Firmware Updates, and Repairability Can Combat E-Waste

    In the relentless pursuit of innovation, the technology industry has developed a dangerous habit: treating hardware as disposable. Every year, millions of perfectly functional devices are abandoned, not because their core components have failed, but because a software update rendered them sluggish, a proprietary part became impossible to source, or a manufacturer simply decided it was time for consumers to upgrade. This cycle has created an environmental crisis of staggering proportions, with e-waste now ranking as the fastest-growing waste stream on the planet. Yet within this challenge lies an opportunity for a fundamental redesign of how we think about product longevity. By focusing on thoughtful user experience, honoring backward compatibility, delivering meaningful firmware updates, and embracing genuine repairability, the tech industry can chart a course toward a more sustainable future without sacrificing progress.

    For a decade, I have written about technology from the perspective of both an enthusiast and a critic, and one truth has become increasingly clear: the most sustainable device is the one that remains useful for years, not the one marketed as “green” at launch. This article explores the intricate connections between five concepts that rarely appear together in product marketing materials but hold the key to breaking our destructive cycle of consumption. Understanding how these elements interact is essential not only for manufacturers and policymakers but also for consumers who want to make responsible choices in a marketplace that often seems designed to prevent them.

    The Hidden Cost of Planned Obsolescence

    Before diving into solutions, it is important to understand the scale of the problem. E-waste is now the world’s fastest-growing domestic waste stream, with the United Nations estimating that over 50 million metric tons are generated annually. To put that in perspective, that is equivalent to throwing away more than 1,000 laptops every single second of every single day. The environmental consequences are severe: e-waste contains hazardous materials such as lead, mercury, and cadmium that leach into soil and groundwater when improperly disposed of, while the energy and resources invested in manufacturing these devices are lost when products are retired prematurely. The carbon footprint of producing a single smartphone is estimated at roughly 70 kilograms of CO2 equivalent, meaning that every unnecessary upgrade carries a significant environmental burden.

    What makes this crisis particularly frustrating is that much of it is preventable. A significant portion of e-waste is not the result of catastrophic hardware failure but rather the result of perceived obsolescence—the feeling that a device has become outdated, slow, or unsupported. This is where the connection between user experience, backward compatibility, firmware updates, and repairability becomes critical. Each of these factors directly influences how long a device remains in active use, and each represents a lever that manufacturers can pull to extend product lifespans and reduce environmental impact. The challenge lies in aligning these levers with business models that historically have depended on frequent upgrades.

    User Experience: The Foundation of Longevity

    At first glance, user experience and sustainability might seem like unrelated concerns. After all, a sleek interface and smooth animations seem more about marketing appeal than environmental responsibility. However, user experience is arguably the single most important factor in determining how long a device remains in service. A device that remains responsive, intuitive, and pleasant to use is far less likely to be replaced than one that frustrates its owner with lag, crashes, or confusing interface changes. When a phone becomes slow after a software update or a laptop struggles to handle routine tasks, users naturally begin shopping for replacements—even if the underlying hardware is fully capable.

    This creates a profound responsibility for manufacturers: design user experiences that are sustainable over time, not just impressive at launch. This means resisting the temptation to layer on resource-intensive features that older hardware cannot handle. It means ensuring that software optimizations are prioritized alongside feature additions. And it means respecting the user’s existing workflows and preferences rather than forcing disruptive redesigns that make devices feel foreign and frustrating. Companies that prioritize long-term user experience understand that every interface decision has environmental consequences. A software update that slows down a million devices does not just annoy users—it contributes to premature obsolescence and the e-waste crisis.

    Unfortunately, the incentives in the tech industry often work against this principle. Product teams are rewarded for shipping new features, not for maintaining performance on older hardware. Marketing departments celebrate flashy redesigns. And business models often depend on convincing users that their current devices are inadequate. Changing this culture requires a fundamental shift in how companies measure success, moving from metrics like “new features shipped” to metrics like “devices still in active use after five years.” When user experience is measured over the full lifecycle of a product, sustainability and satisfaction become mutually reinforcing goals.

    There are encouraging signs that this shift is beginning. Some manufacturers now explicitly advertise that their devices will remain fast and responsive after multiple years of use, backed by software update commitments. Others have introduced performance modes that prioritize battery longevity and thermal management over maximum speed. These are steps in the right direction, but they remain the exception rather than the rule. For user experience to truly become a sustainability tool, it must be embedded in the core design philosophy of every technology company, not treated as an afterthought or a marketing bullet point.

    Backward Compatibility: The Art of Respecting the Past

    Backward compatibility—the ability of new hardware or software to work with older accessories, applications, or formats—is one of the most underappreciated tools in the fight against e-waste. When a new console cannot play games from the previous generation, when a new phone requires entirely new chargers and accessories, or when a software update breaks legacy applications, the result is the same: functional hardware is pushed toward obsolescence. The old devices, accessories, and peripherals join the growing mountain of e-waste, even though they continue to serve their intended purpose perfectly well.

    The history of backward compatibility in consumer technology is instructive. In the gaming industry, Sony’s PlayStation 2 famously supported PlayStation 1 games, making the transition between generations seamless and preserving the value of existing game libraries. Microsoft has followed a similar path with its Xbox consoles, and Nintendo’s support for older titles through its virtual console services has extended the life of classic games and the hardware that runs them. Each of these examples demonstrates that respecting consumers’ existing investments is not just good customer service—it is good environmental stewardship. When users can upgrade their device without discarding their entire ecosystem of accessories and content, the environmental impact of the upgrade is dramatically reduced.

    The same principle applies to software and services. When a new operating system version breaks compatibility with older applications, users face a difficult choice: upgrade their software (and possibly their hardware) or remain on an unsupported platform. For businesses, this can mean replacing entire fleets of computers, scanners, and specialized equipment because a single piece of software no longer works. The environmental cost of these decisions is rarely factored into development roadmaps, but it is very real. Every broken compatibility is a small act of planned obsolescence, even when it is unintentional.

    Critics of backward compatibility often argue that maintaining support for older formats and standards slows innovation and adds complexity. This is a legitimate concern—carrying legacy code and hardware interfaces forward can be technically challenging and resource-intensive. However, the solution is not to abandon backward compatibility entirely but to approach it thoughtfully. Progressive enhancement, graceful degradation, and standardized interfaces can all help extend the useful life of existing products without constraining innovation. Companies that invest in these approaches discover that backward compatibility is not a burden but a competitive advantage, building customer loyalty and reducing the barriers to upgrading to newer products.

    Firmware Updates: Breathing New Life Into Existing Hardware

    Firmware updates represent one of the most powerful yet underutilized tools for extending the lifespan of electronic devices. Unlike software updates that affect applications and operating systems, firmware is the foundational code that controls how hardware functions at its most basic level. This includes everything from the power management system in a laptop to the autofocus algorithms in a camera to the battery charging logic in a smartphone. A well-designed firmware update can transform an aging device, fixing bugs, improving performance, adding features, and even addressing security vulnerabilities that would otherwise force users to replace their hardware.

    The smartphone industry provides compelling examples of both the promise and the peril of firmware updates. On the positive side, some manufacturers have used firmware updates to dramatically improve camera performance, extend battery life through more efficient power management, and patch security vulnerabilities that would otherwise leave devices exposed. These updates can effectively give users a “new” device without any new hardware, saving money and reducing environmental impact. On the negative side, there are equally famous examples of firmware updates that throttled performance, introduced bugs, or deliberately degraded features—usually under the guise of protecting battery health or optimizing performance. When firmware updates are used as tools of planned obsolescence rather than product enhancement, they undermine consumer trust and accelerate the e-waste cycle.

    The key difference between these two approaches lies in the intent behind the update. Updates designed to solve real problems and improve the user experience genuinely extend product lifespans. Updates designed to nudge users toward upgrades or to mask hardware deficiencies are environmental sabotage, pure and simple. Regulators have begun to notice this distinction, with several jurisdictions now requiring manufacturers to disclose update policies and, in some cases, to provide security updates for a minimum number of years. This is a welcome development, but it is only a starting point. Consumers deserve firmware updates that make their devices better over time, not updates that make them worse.

    There is also an important connection between firmware updates and security that is often overlooked in discussions of sustainability. Unpatched security vulnerabilities are a leading cause of premature device retirement, particularly in enterprise environments where data protection regulations require devices to be kept current. When manufacturers end firmware support for a device, they effectively sentence it to obsolescence, even if the hardware remains fully functional. Extending the firmware support window is therefore one of the simplest and most effective ways to reduce e-waste. Every year of additional firmware updates is a year that millions of devices can remain in productive use.

    Repairability: The Right to Fix What You Own

    If firmware updates are the software side of the longevity equation, repairability is the hardware side. Repairability refers to how easily a device can be opened, diagnosed, and repaired when something goes wrong. A device with a user-replaceable battery, standardized screws, and widely available spare parts can be kept in service for years or even decades. A device with glued components, proprietary screws, and unavailable spare parts is one cracked screen or swollen battery away from the landfill. The connection between repairability and e-waste is direct and undeniable: every repair that happens is a device that does not need to be replaced, and every device that cannot be repaired is e-waste waiting to happen.

    The right-to-repair movement has gained significant momentum in recent years, driven by growing awareness of the environmental consequences of disposable electronics. In the United States, several states have passed or are considering laws requiring manufacturers to provide access to repair manuals, diagnostic tools, and spare parts. The European Union has gone further, mandating that certain categories of electronics—including smartphones, tablets, and laptops—meet minimum repairability standards. These regulations are a response to years of manufacturer resistance, including practices such as serialized parts that cannot be replaced without proprietary software, lithium-ion batteries that are glued into cases, and repair programs that are priced so high that replacement is effectively the only economic option.

    However, repairability is about more than just legislation. It is also a design philosophy that prioritizes the long-term relationship between a device and its owner. Companies that embrace repairability understand that their relationship with customers does not end at the point of sale but continues throughout the life of the product. This means designing devices that can be opened without special tools, using standardized components that can be sourced from multiple suppliers, and providing clear documentation that empowers users and independent repair shops. It means treating the repair ecosystem—including independent technicians and third-party parts suppliers—as partners in sustainability rather than competitors to be eliminated.

    The benefits of repairability extend far beyond environmental sustainability. Repairable devices are more valuable to their owners, leading to stronger brand loyalty and customer satisfaction. They create local economic opportunities through independent repair businesses. And they reduce the demand for new raw materials, including the rare earth elements and conflict minerals that are associated with significant environmental and human rights concerns. Every repair that happens is a small victory for sustainability, and every device designed for repairability is a device that is more likely to be repaired.

    Finding the Balance: A Framework for Sustainable Technology

    The relationship between these five concepts—user experience, backward compatibility, firmware updates, e-waste, and repairability—is complex and sometimes contradictory. Longer software support periods can strain hardware resources, potentially degrading user experience. Backward compatibility can add complexity that makes devices harder to repair. Firmware updates can introduce security improvements but also performance regressions. Navigating these trade-offs requires a holistic approach that considers the entire lifecycle of a product, from design and manufacturing through years of use and eventual retirement.

    One useful framework is to think of sustainability as a design constraint rather than a marketing attribute. Just as engineers balance cost, size, and power consumption, they should also balance longevity, repairability, and environmental impact. This means making explicit decisions about product lifespans, update policies, and repair support at the beginning of the design process, not as afterthoughts. It means measuring success not just by units sold but by the total environmental impact per year of useful life. And it means being honest with consumers about what they can expect from their devices over time.

    The business case for this approach is stronger than many manufacturers acknowledge. Consumers are increasingly aware of the environmental impact of their technology purchases and are willing to pay a premium for products that are built to last. The success of companies like Fairphone, which has built a business around repairable, long-lasting smartphones, demonstrates that there is real demand for sustainable alternatives. Meanwhile, the regulatory environment is shifting in favor of longevity, with requirements for longer update support, easier repairs, and clearer disclosure of environmental impact. Companies that embrace sustainability now will be ahead of the curve, while those that resist will find themselves scrambling to adapt.

    Consumers also have a role to play. By choosing products with long update commitments, supporting right-to-repair legislation, and resisting the urge to upgrade whenever a new model is released, individuals can send a powerful signal to manufacturers. Every purchase decision is a vote for the kind of technology industry we want to have. And while individual actions alone cannot solve the e-waste crisis, collective consumer pressure has repeatedly proven capable of shifting corporate behavior. The most sustainable device is the one you already own—and the second most sustainable is one designed to last for years, not months.

    Conclusion: Designing for the Long Term

    The e-waste crisis is not an inevitable consequence of technological progress. It is the result of specific design decisions, business models, and consumer behaviors that prioritize short-term gains over long-term sustainability. By rethinking these decisions—by prioritizing user experience over feature bloat, honoring backward compatibility, delivering meaningful firmware updates, and embracing genuine repairability—the technology industry can dramatically reduce its environmental footprint while still delivering innovative products that improve people’s lives. The tools and knowledge needed to solve this problem already exist; what is missing is the will to put them into practice.

    As consumers, as professionals, and as citizens, we all have a stake in this transition. The devices we use every day are not just tools—they are expressions of our values and our vision for the future. When we demand products that are designed to last, supported over time, and repairable when things go wrong, we are not just reducing e-waste. We are creating a technology industry that serves people and the planet, not just quarterly earnings reports. The path to a sustainable future is paved with devices that remain useful, valuable, and loved for years after they leave the factory. That is a future worth building, one firmware update, one repair, and one thoughtful design decision at a time.

  • Neural Networks in Practice: Balancing Training Data, Fine-Tuning, Prompt Engineering, and Inference Cost

    Neural Networks in Practice: Balancing Training Data, Fine-Tuning, Prompt Engineering, and Inference Cost

    Neural networks have become the backbone of modern artificial intelligence, powering everything from voice assistants and recommendation engines to advanced medical imaging and generative writing tools. Yet behind every successful neural network deployment lies a careful orchestration of four essential elements: training data, fine-tuning, prompt engineering, and inference cost. Understanding how these components interact is no longer optional for technical teams—it is the difference between a model that performs brilliantly in a demo and one that delivers reliable, cost-effective value in production. This article explores each of these pillars in depth, offering practical insights for practitioners who want to get the most out of neural network systems.

    1. The Foundation: How Neural Networks Learn from Training Data

    At its most basic level, a neural network is a computational system inspired by the structure of the human brain. It consists of layers of interconnected nodes, or neurons, that process information by assigning weights to inputs and passing results through activation functions. During training, the network adjusts these weights to minimize the difference between its predictions and the correct answers. This learning process is entirely dependent on the quality and character of the training data provided to the model. Without well-curated training data, even the most advanced neural network architecture will fail to generalize to real-world tasks.

    The first principle of effective training data is relevance. A neural network trained on general web text will not automatically understand the specialized vocabulary of legal contracts, medical records, or industrial maintenance logs. The data must reflect the domain where the model will be used. For example, a customer support neural network for a telecommunications company should include transcripts of real customer interactions, including complaints, troubleshooting steps, and billing questions. If the training data is too generic, the model will produce plausible-sounding but ultimately inaccurate responses.

    Quality is equally important as relevance. Real-world datasets are often messy, containing duplicate records, inconsistent formatting, and human errors. A neural network learns statistical patterns from whatever it is given, so noisy labels or contradictory examples can degrade performance. Many teams spend more time cleaning and validating training data than they do designing model architecture. This is not wasted effort—several studies have shown that improving data quality often yields larger performance gains than increasing model size. In practical terms, this means removing irrelevant entries, standardizing text formats, and ensuring that human annotators agree on labeling guidelines before training begins.

    What Makes Training Data Effective?

    High-quality training data for neural networks typically exhibits several key characteristics:

    • Relevance: The data closely matches the target domain and task.
    • Diversity: It covers a wide range of scenarios, edge cases, and user inputs.
    • Accuracy: Labels and expected outputs are correct and consistent.
    • Volume: There is enough data for the model to learn meaningful patterns.
    • Balance: Classes or response types are not heavily skewed unless the real-world distribution demands it.

    Bias in training data is a persistent concern. Neural networks are pattern-matching machines, and they will amplify any social, cultural, or statistical biases present in their training examples. For instance, a hiring recommendation model trained on historical data that underrepresents certain groups may learn to discriminate against those groups. Addressing this requires deliberate sampling strategies, fairness audits, and sometimes synthetic data generation to fill gaps. The goal is not only to avoid legal or ethical problems but also to build models that perform well for all users, not just the majority subset represented in the original dataset.

    Another emerging trend is the use of synthetic training data. When real data is scarce, sensitive, or expensive to collect, teams can generate artificial examples using other neural networks or rule-based systems. Synthetic data can be especially useful for simulating rare events, such as fraud attempts or equipment failures, that may be underrepresented in historical records. However, synthetic data must be used cautiously because it can introduce new biases or fail to capture the full complexity of real-world inputs. The best approach is often a hybrid: combine a large volume of real data with targeted synthetic examples that address specific gaps.

    2. Fine-Tuning: Adapting Pre-Trained Neural Networks to Your Domain

    Training a large neural network from scratch is an enormously expensive undertaking. It requires vast amounts of data, specialized hardware, and significant time. This is why fine-tuning has become the standard approach for most practical applications. Fine-tuning begins with a pre-trained model that has already learned general language understanding, visual features, or other fundamental patterns from a large corpus. The model is then further trained on a smaller, domain-specific dataset to adapt its behavior to a particular task. This process is a form of transfer learning and dramatically reduces the amount of data and compute required to achieve strong performance.

    For example, a general-purpose language model trained on billions of web pages can be fine-tuned on a few thousand examples of medical question-answer pairs to become a reasonably competent medical assistant. The pre-trained model already understands grammar, reasoning, and common world knowledge. Fine-tuning teaches it the specific terminology, style, and constraints of the medical domain. Without the pre-trained foundation, the same medical assistant would require millions of labeled examples and far more computational power to reach a similar level of performance.

    When Should You Fine-Tune?

    Fine-tuning is not always necessary. In many cases, a well-engineered prompt on a general model is sufficient. However, fine-tuning becomes valuable when you encounter the following conditions:

    • Domain-specific language: The model must understand jargon, acronyms, or conventions not common in general training data.
    • Consistent output format: You need the model to always return structured data, such as JSON, XML, or a specific template.
    • Behavioral control: The model must follow company-specific policies, tone guidelines, or safety rules.
    • Performance improvement: Prompting alone does not reach the required accuracy or reliability.
    • Cost reduction: A smaller fine-tuned model may outperform a much larger general model, reducing inference cost.

    Modern fine-tuning techniques have evolved to be more parameter-efficient. Full fine-tuning updates all the weights in a neural network, which requires significant memory and compute. In contrast, methods like LoRA (Low-Rank Adaptation) introduce small trainable matrices that adapt the model’s behavior without modifying the original weights. This reduces the hardware requirements and makes it easier to maintain multiple fine-tuned versions for different tasks. Another benefit of parameter-efficient fine-tuning is that it helps mitigate catastrophic forgetting, where a model loses previously learned abilities after being trained on new data.

    Fine-tuning also requires its own training data considerations. While the dataset can be much smaller than what is needed for training from scratch, it must be carefully curated. A few thousand high-quality, diverse examples often yield excellent results for many language and image tasks. Teams should include both positive examples that demonstrate desired behavior and negative examples that show what the model should avoid. Evaluation during fine-tuning is essential—monitor metrics on a held-out validation set to prevent overfitting, where the model memorizes the training examples but fails to generalize to new inputs.

    3. Prompt Engineering: Guiding Neural Networks Without Retraining

    Prompt engineering is the practice of designing input text or instructions to elicit the desired output from a generative neural network. Instead of changing the model’s weights through fine-tuning, prompt engineering works entirely at inference time. It relies on the model’s pre-existing knowledge and reasoning abilities, directing them through carefully chosen words, examples, and structure. This makes it one of the most accessible and cost-effective ways to customize a neural network’s behavior, because it requires no additional training data or GPU hours.

    The simplest form of prompt engineering is zero-shot prompting, where the user asks the model to perform a task without providing any examples. For instance, a prompt like “Classify the following review as positive or negative: ‘The battery life is disappointing’” asks the model to perform sentiment analysis using only its pre-trained understanding. If the task is more complex or the model struggles with zero-shot performance, few-shot prompting adds a small number of examples within the prompt. These examples help the model infer the pattern and format expected for the task.

    Core Prompt Engineering Strategies

    Effective prompt engineering involves more than writing a clear instruction. Experienced practitioners use a range of techniques to improve reliability and accuracy:

    • Chain-of-thought prompting: Ask the model to reason step by step before giving a final answer. This improves performance on arithmetic, logic, and multi-step reasoning tasks.
    • Role assignment: Tell the model to adopt a specific persona, such as “You are an experienced financial analyst.” This can shape tone and domain focus.
    • Output formatting instructions: Specify the exact format, such as “Return the result as a JSON object with keys ‘sentiment’ and ‘confidence’.”
    • Example selection: Choose few-shot examples that are diverse, representative, and clearly labeled to reduce ambiguity.
    • Iterative refinement: Start with a basic prompt, evaluate outputs, and adjust wording, examples, or constraints until the model behaves as desired.

    Prompt engineering is not a replacement for fine-tuning in all cases. It works best when the task is already well-represented in the model’s training data and when the desired behavior can be described in natural language. For highly specialized domains or strict output requirements, prompt engineering alone may be brittle. Small changes in phrasing can lead to inconsistent results, and long prompts with many examples increase the number of input tokens, which raises inference cost. Nevertheless, prompt engineering is an indispensable tool for rapid prototyping, evaluating model capabilities, and building applications on top of general-purpose neural networks.

    Another important aspect of prompt engineering is managing the model’s context window. Neural networks with transformer architectures have a maximum length for the combined input and output tokens. Long prompts consume part of that capacity and can reduce the space available for the actual output. Practitioners must balance the need for detailed instructions and examples with the cost and context limitations. This is especially relevant when using third-party APIs that charge per token, where a verbose prompt directly increases operational expenses.

    4. Inference Cost: The Hidden Economics of Neural Network Deployment

    While much attention is given to training neural networks, the ongoing cost of inference—running the model on new inputs—often dominates the total cost of ownership in production systems. Inference cost includes the computational resources, memory, and energy required to generate predictions or outputs. For a model that serves millions of users per day, even small inefficiencies in inference can translate into substantial cloud bills and degraded user experiences due to latency.

    The primary driver of inference cost is model size. Larger neural networks with billions or trillions of parameters require more memory and more floating-point operations for each prediction. This is why frontier language models are often expensive to run at scale. A model with 175 billion parameters cannot fit on a single consumer GPU and may require multiple high-end accelerators just to serve a single request within a reasonable time. As model size increases, the cost per token or per image can rise dramatically, forcing organizations to make trade-offs between capability and affordability.

    Factors That Influence Inference Cost

    Several technical and operational factors determine how expensive it is to run a neural network in production:

    • Model architecture and parameter count: Larger models require more compute and memory per inference.
    • Input and output length: For language models, longer prompts and generated responses increase the number of tokens processed.
    • Hardware: GPUs, TPUs, and specialized inference chips vary widely in cost and efficiency.
    • Batching: Processing multiple requests together improves throughput but can increase latency.
    • Precision: Running models with lower numerical precision, such as 8-bit or 4-bit quantization, reduces memory and compute requirements.
    • Caching: Storing responses for common queries can eliminate redundant inference calls.

    Reducing inference cost is a major focus for teams deploying neural networks at scale. Quantization is one of the most effective techniques. It converts the model’s weights and activations from high-precision floating-point numbers to lower-precision formats. A model quantized from 16-bit to 4-bit can run much faster and use less memory, often with only a small drop in accuracy. Another approach is distillation, where a smaller “student” model is trained to mimic the behavior of a larger “teacher” model. The student model can achieve comparable performance on a specific task while being dramatically cheaper to run.

    Hardware selection also plays a critical role. General-purpose GPUs are versatile but may not be the most cost-effective option for production inference. Many cloud providers now offer specialized inference accelerators optimized for transformer models, reducing latency and cost per request. For smaller models, running inference on CPUs or edge devices can be sufficient, eliminating the need for expensive GPU instances altogether. Careful capacity planning and autoscaling help ensure that you are not paying for idle compute during low-traffic periods.

    Inference cost is not merely a technical concern; it shapes product strategy. A feature that calls a massive neural network for every user interaction may become prohibitively expensive at scale. Teams often use a tiered approach: a small, fast model handles common cases, while a larger, more capable model is invoked only for difficult or high-value requests. This hybrid strategy balances quality and cost, ensuring that the user experience remains responsive without exhausting the budget.

    5. Choosing the Right Approach: A Decision Framework

    The relationship between training data, fine-tuning, prompt engineering, and inference cost is not sequential—it is a continuous balancing act. The right approach depends on your specific goals, data availability, performance requirements, and budget. The following framework can help guide your decision-making:

    • If you have a large, high-quality labeled dataset and a unique task: Consider training a smaller neural network from scratch or fine-tuning a pre-trained model. This is appropriate when prompt engineering cannot capture domain-specific complexity.
    • If you have modest data but need domain customization: Fine-tune a pre-trained model using parameter-efficient methods like LoRA. This delivers strong domain adaptation without the cost of full training.
    • If you need rapid deployment with no training data: Start with prompt engineering on a general-purpose model. Build a prompt library, evaluate outputs, and only move to fine-tuning if performance plateaus.
    • If inference cost is a major constraint: Explore model distillation, quantization, and caching. A smaller fine-tuned model may outperform a large general model at a fraction of the cost.
    • If your task involves sensitive or rapidly changing data: Avoid training on stale data. Use prompt engineering or retrieval-augmented generation to keep outputs current without constant retraining.

    Successful teams often iterate across these approaches. They may begin with prompt engineering to test the feasibility of a feature, then fine-tune a smaller model once they have collected production data, and finally optimize inference cost through quantization and batching. Throughout this process, evaluation is essential. Define clear success metrics—accuracy, latency, cost per request, user satisfaction—and measure them continuously. Neural networks are not static artifacts; they require ongoing monitoring and improvement as data distributions shift and user expectations evolve.

    6. The Future of Neural Network Efficiency

    The landscape of neural networks is shifting rapidly toward greater efficiency and accessibility. Researchers are developing new architectures that achieve state-of-the-art results with fewer parameters and lower inference costs. Techniques like mixture-of-experts allow models to activate only a small subset of their weights for each input, reducing compute while maintaining capacity. Parameter-efficient fine-tuning methods continue to improve, making it possible to adapt large models on consumer hardware. At the same time, prompt engineering is becoming more systematic, with tools that automatically optimize prompts and manage context windows.

    Another important trend is the move toward on-device inference. As mobile processors and dedicated AI chips become more powerful, neural networks that once required cloud GPUs can now run locally on smartphones and laptops. This reduces latency, improves privacy, and eliminates the marginal cost of cloud inference. However, on-device models must be smaller and more efficient, which increases the importance of distillation, quantization, and careful training data selection. The same principles apply to edge computing in industrial settings, where neural networks monitor equipment or analyze sensor data in real time without relying on a stable internet connection.

    Organizations that understand the interplay between training data, fine-tuning, prompt engineering, and inference cost will be better positioned to capitalize on these advances. Rather than treating each element as a separate discipline, the most effective teams view them as levers that can be adjusted in concert. A small, well-tuned model with a carefully engineered prompt can often match or exceed the performance of a much larger, more expensive system—if the training data is aligned with the task and the inference pipeline is optimized.

    Conclusion

    Neural networks are powerful tools, but their real-world value depends on much more than raw model architecture. Training data supplies the knowledge, fine-tuning adapts that knowledge to specific domains, prompt engineering shapes behavior without retraining, and inference cost determines whether the solution is economically viable. By understanding each of these components and how they interact, practitioners can build AI systems that are not only accurate but also scalable, reliable, and cost-effective.

    Whether you are launching a new AI-powered product or optimizing an existing deployment, take the time to evaluate your training data quality, consider whether fine-tuning or prompting is the better fit, and measure your inference costs under realistic load. The most successful neural network applications are rarely the result of a single breakthrough—they are the product of thoughtful engineering across the entire machine learning lifecycle. With a balanced approach to these four pillars, you can unlock the full potential of neural networks while keeping your project efficient and sustainable.

  • Breaking the Chains: How Interoperability and End-to-End Encryption Protect You from Vendor Lock-In, Zero-Day Exploits, and Ransomware

    Breaking the Chains: How Interoperability and End-to-End Encryption Protect You from Vendor Lock-In, Zero-Day Exploits, and Ransomware

    For years, the digital world has promised seamless connectivity, unlimited productivity, and ironclad security. Yet many organizations and individuals find themselves trapped in digital ecosystems that feel more like gated communities than open landscapes. The cost of convenience often comes in the form of vendor lock-in, where switching from one software provider to another becomes an expensive, technically complex nightmare. At the same time, the threat landscape has evolved dramatically. Zero-day vulnerabilities lurk beneath the surface of trusted applications, and ransomware attacks have become a multi-billion-dollar criminal enterprise. Meanwhile, end-to-end encryption remains one of the most misunderstood and underutilized tools for protecting sensitive information. Understanding how these concepts intersect is no longer just an IT concern—it is essential for anyone who relies on digital systems to live, work, or communicate.

    The relationship between these five keywords—interoperability, vendor lock-in, zero-day, ransomware, and end-to-end encryption—is more connected than most people realize. Vendor lock-in can worsen the impact of a zero-day vulnerability because organizations may be unable to patch quickly or switch to a safer alternative. Ransomware operators often exploit unpatched zero-day flaws to gain initial access. End-to-end encryption can protect data even when a network is compromised, but it cannot save an organization from a ransomware attack if the attackers already control the endpoints. Interoperability, on the other hand, gives organizations the freedom to diversify their tools, reduce dependence on a single vendor, and respond more effectively when a critical vulnerability is discovered. This article explores each concept in depth and offers a practical framework for building a resilient, secure digital strategy.

    In an era where digital sovereignty is becoming as important as physical security, the choices you make about software, data storage, and communication platforms have long-term consequences. The goal is not to abandon all proprietary tools or live in constant fear of zero-day exploits. Instead, the goal is to understand the trade-offs, demand better standards, and adopt a security posture that does not depend on a single vendor’s promises. By embracing interoperability and end-to-end encryption, you can reduce the damage caused by vendor lock-in, mitigate the risk of zero-day attacks, and build stronger defenses against ransomware. Let’s break it down.

    The Hidden Cost of Closed Ecosystems

    Vendor lock-in occurs when a customer becomes dependent on a vendor for products or services and cannot easily move to another vendor without substantial switching costs. Those costs can be financial, technical, or operational. A company that has built its entire data pipeline on a proprietary cloud platform may find that exporting data, retraining staff, and rewriting integrations would cost more than simply staying put—even if the vendor raises prices or suffers repeated security breaches. This lack of leverage is not an accident. Many software providers deliberately design their systems to make data export difficult, APIs limited, or file formats proprietary. The result is a digital cage disguised as convenience.

    For individual users, vendor lock-in often looks like a notes app that refuses to export in a standard format, a smart home hub that only works with certain devices, or a messaging platform that cannot communicate with users on other apps. For enterprises, lock-in can mean thousands of custom integrations tied to a single customer relationship management system, or critical infrastructure that depends on one cloud provider’s proprietary security model. In each case, the user loses control over their own data and decision-making. When a vendor is acquired, goes out of business, or suffers a massive security incident, the locked-in customer is left scrambling.

    Interoperability is the antidote to vendor lock-in. It refers to the ability of different systems, applications, and devices to exchange and use information seamlessly, often through open standards and well-documented APIs. Interoperable systems allow you to choose the best tool for each job without being penalized for future migrations. For example, an email client that supports standard protocols like IMAP and SMTP can work with nearly any email provider, giving users the freedom to switch hosts without losing access to their archived messages. A cloud platform that exposes open APIs and supports container standards enables organizations to move workloads between providers or bring them in-house when needed.

    The benefits of interoperability extend beyond convenience. When systems are interoperable, competition increases, prices become more reasonable, and innovation accelerates because no single vendor can hold customers hostage. Security also improves because organizations can diversify their infrastructure. A zero-day vulnerability in one vendor’s product does not automatically compromise the entire operation if other components come from different providers and communicate through open standards. In short, interoperability is not just a technical nice-to-have; it is a strategic advantage that directly impacts security, cost, and resilience.

    • Data portability: The ability to export your data in standard, readable formats whenever you choose.
    • API access: Well-documented application programming interfaces that allow third-party tools to integrate transparently.
    • Open standards: Publicly available specifications that ensure different products can work together without custom code.
    • Modular architecture: The freedom to replace individual components without rebuilding the entire system.

    Zero-Day Vulnerabilities: When the Unknown Strikes

    A zero-day vulnerability is a security flaw in software or hardware that is unknown to the vendor and therefore has no official patch or fix available. The term “zero-day” refers to the fact that developers have had zero days to address the vulnerability before it is exploited. Attackers who discover zero-day flaws can use them to bypass security controls, steal data, install malware, or gain unauthorized access to systems. Because there is no patch, traditional defenses like antivirus signatures and routine update policies are often ineffective. Zero-day exploits are prized by cybercriminals and nation-state actors alike because they offer a window of opportunity to compromise targets before anyone knows the flaw exists.

    Zero-day vulnerabilities are not rare, theoretical concerns. They are regularly discovered in popular operating systems, browsers, and enterprise software. When a zero-day is discovered in the wild, the vendor rushes to release a patch, but the race between the fix and the attackers can leave millions of systems exposed for days, weeks, or even months. Organizations that rely on a single vendor’s ecosystem are particularly vulnerable because one zero-day in that vendor’s platform can compromise the entire environment. Vendor lock-in makes it difficult to quickly switch to an alternative product or isolate the vulnerable component, turning a single flaw into a systemic crisis.

    Why Zero-Days Thrive in Monocultures

    A digital monoculture is an environment where the vast majority of systems run the same software, often from the same vendor. While standardization can simplify management, it also creates a single point of failure. A zero-day vulnerability in a widely used operating system or application becomes a global attack vector because so many organizations depend on the same code base. Attackers can develop an exploit once and deploy it against thousands or even millions of targets. Interoperability can help break up these monocultures by allowing organizations to run a diverse mix of tools that communicate through open standards. If one component is compromised, the rest of the ecosystem can continue to function, and the affected component can be replaced more easily.

    Diversity in software and hardware is not a perfect defense, but it raises the cost and complexity of attacks. When an organization uses interoperable systems from multiple vendors, an attacker who exploits a zero-day in one product still has to overcome additional layers of defense from other products. This concept, known as defense in depth, is much harder to achieve when a single vendor controls the entire stack. Interoperability gives you the freedom to implement layered security without being locked into a single vendor’s security model.

    • Zero-day flaws have no vendor patch at the time of discovery.
    • Monocultures amplify the impact of a single zero-day exploit.
    • Interoperability enables a diverse, layered defense strategy.
    • Rapid replacement of vulnerable components is possible when systems are not locked in.

    Ransomware: The Weapon of Choice for Modern Criminals

    Ransomware is a type of malicious software that encrypts a victim’s files or systems and demands payment, usually in cryptocurrency, in exchange for the decryption key. Over the past decade, ransomware has evolved from a nuisance into a highly organized criminal enterprise. Attackers no longer rely on simple phishing emails alone. They now combine social engineering, credential theft, and the exploitation of zero-day vulnerabilities to gain initial access to corporate networks. Once inside, they move laterally, escalate privileges, and deploy ransomware across the entire environment, often exfiltrating sensitive data first and threatening to publish it if the ransom is not paid.

    The rise of ransomware has forced organizations to rethink their backup strategies, incident response plans, and vendor relationships. A common mistake is assuming that paying the ransom will quickly restore normal operations. In reality, even when victims pay, they often receive faulty decryption tools, face repeat attacks, or discover that their data has been corrupted. The best defense is a combination of robust backups, network segmentation, timely patching, and a security architecture that assumes breaches will happen. However, vendor lock-in can severely undermine these efforts. If your backups are stored in a proprietary format tied to one vendor, and that vendor’s systems are also encrypted, your recovery options shrink dramatically.

    How Lock-In Amplifies Ransomware Damage

    Imagine an organization that stores all of its critical data in a single proprietary cloud platform. The platform offers convenience, automatic updates, and built-in security—but it also creates a single point of failure. When attackers compromise an administrator account, they can encrypt the cloud environment, delete backups, and lock the organization out of its own systems. Because the data is stored in a proprietary format with limited export capabilities, the organization cannot easily migrate to another provider or rebuild its infrastructure using independent backups. The ransomware attack becomes a business-ending event not just because of the encryption, but because of the lack of interoperability.

    An interoperable environment, by contrast, allows you to maintain backups in standard formats on independent storage systems. You can segment your network so that a compromise in one area does not spread to every system. You can replace a compromised application with an alternative without rebuilding your entire workflow. You can even store encrypted backups with a different provider or on offline media, ensuring that a ransomware attack cannot destroy your recovery plan. This is why interoperability and ransomware resilience are deeply connected. The more portable your data and the more modular your infrastructure, the less leverage attackers have over you.

    Ransomware operators also exploit zero-day vulnerabilities to bypass security tools and gain a foothold. When a zero-day in a widely used remote access tool or firewall is discovered, attackers rush to exploit it before patches are widely deployed. Organizations that rely on a single vendor for security, networking, and data storage face a compounding risk: a zero-day in that vendor’s product can disable their security controls and encrypt their data in one coordinated strike. Interoperability reduces this risk by allowing you to use security tools from multiple vendors, each with different strengths and update cycles, making it harder for attackers to neutralize your entire defense stack at once.

    End-to-End Encryption: Your Digital Vault

    End-to-end encryption (E2EE) is a method of encrypting data so that only the sender and the intended recipient can read it. Unlike encryption in transit or at rest, where a service provider may hold the decryption keys, E2EE ensures that the keys remain exclusively on the user’s devices. This means that even if a malicious actor intercepts the data in transit, compromises the server, or coerces the service provider, they cannot decrypt the content. E2EE is the gold standard for protecting private communications, sensitive documents, and any data that must remain confidential even against sophisticated adversaries.

    E2EE is often associated with messaging apps, but its applications extend far beyond chat. It can protect file storage, email, video conferencing, and even cloud backups. The key principle is that encryption happens on the sender’s device and decryption happens only on the recipient’s device. The service provider acts as a dumb pipe, relaying ciphertext without ever seeing the plaintext. This architecture dramatically reduces the attack surface because a server breach does not expose user content. For organizations worried about ransomware, E2EE can protect data stored in cloud backups even if the cloud provider is compromised—provided the encryption keys are managed independently and securely.

    What E2EE Really Protects

    • Confidentiality of content: Even if a zero-day flaw exposes server data, ciphertext remains unreadable without user-held keys.
    • Privacy from service providers: The platform cannot access or monetize your data because it lacks the decryption keys.
    • Resistance to coercion: Providers cannot hand over plaintext data to authorities or attackers because they do not possess it.
    • Backup integrity: Encrypted backups maintain their security even if the storage infrastructure is breached.

    However, E2EE is not a magic shield against all threats. If an attacker compromises an endpoint—such as a user’s laptop or phone—they can often read the decrypted data because the keys are present on that device. Ransomware can also encrypt data that is already decrypted on a local machine, so E2EE does not prevent ransomware from locking up files that the user is actively working with. This is why E2EE must be combined with other security measures, including strong endpoint protection, regular offline backups, and a commitment to interoperability that allows you to recover quickly when an endpoint is compromised. Nevertheless, E2EE remains a critical layer of defense, particularly when data is stored or transmitted through third-party infrastructure.

    How Interoperability Defeats Vendor Lock-In

    Interoperability is the most effective tool for breaking the chains of vendor lock-in. When your systems speak open standards, you can migrate data, replace tools, and integrate new services without being held hostage by proprietary formats or closed APIs. This freedom transforms your relationship with vendors from one of dependency to one of partnership. You stay with a vendor because they provide value, not because leaving would be too costly or technically impossible. That dynamic alone creates powerful incentives for vendors to improve security, respect user privacy, and respond quickly to vulnerabilities like zero-days. A vendor that knows you can walk away is far more accountable than one that knows you are trapped.

    Interoperability also enables what security experts call “security through diversity.” Instead of entrusting every layer of your digital life to a single provider, you can mix and match best-of-breed tools that communicate through open protocols. For example, you might use one provider for email, another for cloud storage, and a third for encrypted messaging. If a zero-day vulnerability is discovered in your email provider’s software, your encrypted messaging and cloud storage remain unaffected. If your cloud storage provider suffers a ransomware attack, you can switch to another provider using data exported from your independent backups. This modularity reduces the blast radius of any single security failure and makes you a much harder target for attackers.

    Many organizations fear that interoperability means sacrificing features or ease of use. In the past, proprietary software often offered superior integrations and polished user experiences because everything was designed to work together. Today, however, open standards have matured to the point where interoperable systems can be just as seamless as closed ecosystems. The rise of REST APIs, OAuth for authentication, and open container standards has made it easier than ever to build a modern, flexible technology stack without locking yourself into a single vendor. The key is to prioritize interoperability at the procurement stage, before you have invested years of data and custom integrations into a closed platform.

    • Always ask about export options: Can you get your data out in a standard format at any time?
    • Demand open APIs: Does the vendor support third-party integrations without restrictive licensing?
    • Prefer open standards: Look for products that use protocols like CalDAV, CardDAV, OpenID Connect, or Matrix.
    • Test migration paths: Before committing, simulate a migration to ensure you are not secretly locked in.

    The Interplay: Interoperability, Zero-Days, Ransomware, and Encryption

    These five concepts do not exist in isolation. They form a complex web of trade-offs and dependencies. Vendor lock-in increases the damage of a zero-day exploit because you cannot easily switch away from the vulnerable product. Ransomware operators love locked-in environments because recovering without paying is so painful. Interoperability reduces both the likelihood and the impact of these attacks by giving you options. End-to-end encryption protects your data from prying eyes, but it works best when combined with interoperable backup systems and a diverse security stack. Ignoring any one of these elements weakens the whole.

    Consider a real-world scenario. A company uses a proprietary cloud suite for email, file storage, collaboration, and backups. A zero-day vulnerability is discovered in the suite’s web server, and attackers exploit it to deploy ransomware across the company’s entire environment. The company cannot access its files, and its backups—stored in the same proprietary cloud—are also encrypted because the attackers escalated privileges to the backup console. The vendor is slow to release a patch and offers no way to export the remaining metadata. The company faces a choice: pay a massive ransom or lose years of data. Now imagine the same company had used interoperable tools from multiple vendors, kept offline backups in standard formats, and encrypted sensitive files with E2EE. The zero-day would have affected only one component, the ransomware would not have spread to every system, and the offline backups would have allowed recovery without paying a cent.

    The difference between these two outcomes is not luck. It is the result of deliberate architectural decisions made long before the attack. Interoperability creates options. End-to-end encryption creates confidentiality even when infrastructure is compromised. Vigilance against zero-days creates a faster response capability. Together, they form a security posture that is far greater than the sum of its parts. And crucially, they all depend on a mindset that values freedom, diversity, and resilience over short-term convenience and vendor promises.

    Building a Resilient Digital Strategy

    Building a resilient digital strategy requires a shift in how you evaluate technology. Instead of asking, “Does this tool work today?” you must also ask, “Will I be able to leave this tool tomorrow?” Instead of trusting a vendor’s security marketing, you must verify that their architecture supports open standards, transparent data handling, and strong encryption. And instead of waiting for a ransomware attack to expose your weaknesses, you must proactively design your systems so that a single vulnerability does not bring everything down.

    The following practices can help you integrate interoperability, zero-day readiness, ransomware defense, and end-to-end encryption into a cohesive strategy:

    • Prioritize open standards: Choose tools that support standard protocols and file formats so your data remains portable.
    • Demand export capabilities: Before adopting any platform, verify that you can export all your data in a usable format at any time.
    • Adopt end-to-end encryption: Use E2EE for sensitive communications and files, and manage your own encryption keys where possible.
    • Maintain offline backups: Keep at least one backup copy on offline media or in a separate cloud provider using standard, encrypted formats.
    • Patch promptly but verify: Apply security updates quickly, but use multiple layers of defense so a zero-day in one layer does not become catastrophic.
    • Segment your network: Isolate critical systems so a compromise in one area does not automatically spread to others.
    • Test your incident response: Regularly simulate ransomware attacks and zero-day exploits to ensure your recovery plan actually works.
    • Educate your team: Help everyone understand the risks of vendor lock-in and the importance of interoperability and encryption.

    It is also important to recognize that no single vendor can solve all your security problems. The most secure organizations are not those that buy the most expensive security suite, but those that design their systems with the assumption that breaches will happen. They diversify their tools, protect their data with encryption, and maintain the freedom to move when a vendor fails them. This is the essence of digital resilience: not hoping that nothing bad happens, but being ready for when it does.

    Conclusion

    The digital landscape is full of promises—of seamless integration, ironclad security, and effortless management. But beneath those promises often lie hidden dangers: vendor lock-in that strips you of control, zero-day vulnerabilities that strike without warning, and ransomware attacks that exploit every weakness in your architecture. The good news is that you can fight back by embracing interoperability and end-to-end encryption. These are not just technical buzzwords; they are the foundation of a free, resilient, and secure digital future.

    By choosing interoperable systems, you retain the power to move, adapt, and survive when a vendor fails or a vulnerability emerges. By implementing end-to-end encryption, you ensure that your most sensitive data remains private even when the infrastructure around it is compromised. Together, these principles help you break the chains of proprietary lock-in and build a digital life that is truly your own. The next time you evaluate a new tool or platform, ask the hard questions about exportability, open standards, and encryption. Your future security depends on the choices you make today.

  • Latency, Bandwidth, Encryption, APIs, Open Source, and Scalability: The Complete Guide to Building Modern Web Infrastructure

    Latency, Bandwidth, Encryption, APIs, Open Source, and Scalability: The Complete Guide to Building Modern Web Infrastructure

    Every successful web application, whether it is a small startup API or a global enterprise platform, depends on a delicate balance between speed, security, and growth. For developers and architects, the terms latency, bandwidth, encryption, API, open source, and scalability are not just buzzwords. They represent the core pillars that determine whether a digital product feels instant and reliable or slow and fragile. A user does not care about your server configuration, but they will abandon a page that takes more than a few seconds to load. A business does not care about your code elegance, but it will feel the pain when infrastructure costs skyrocket or a security breach exposes customer data. This article explores how these six critical concepts interact, how to optimize each one, and how to design systems that remain fast, secure, and maintainable as they grow.

    Understanding Latency and Bandwidth

    Before optimizing any system, you must understand the difference between latency and bandwidth. They are often confused because both relate to network performance, but they measure different things. Latency is the time it takes for a data packet to travel from one point to another. It is usually measured in milliseconds. Bandwidth is the maximum amount of data that can be transferred over a connection in a given time, typically measured in megabits per second or gigabits per second. Think of a highway: latency is how long it takes a single car to reach its destination, while bandwidth is how many cars can travel on the highway at once. A network can have high bandwidth but terrible latency, or vice versa.

    What Causes Latency?

    Latency is affected by several factors, including physical distance, routing inefficiencies, network congestion, and the processing time of intermediate devices. When a user in New York requests data from a server in Singapore, the signal must travel through thousands of miles of fiber optic cables, often crossing multiple routers and switches. Each hop adds a small delay. Even at the speed of light, a round trip between continents can easily exceed 150 milliseconds. That does not include the time spent by the server processing the request, querying a database, or encrypting the response. Reducing latency often requires moving data closer to users through content delivery networks, optimizing server response times, and minimizing the number of network round trips.

    What Limits Bandwidth?

    Bandwidth is limited by the physical medium of the connection, the capacity of network interfaces, and the amount of traffic competing for the same resources. A fiber optic cable can carry much more data than a copper telephone line. However, even a high-capacity connection can become saturated if too many users request large files simultaneously. Bandwidth is especially important for applications that serve media, large datasets, or high-resolution images. While upgrading bandwidth can improve throughput, it does not solve latency problems. If a connection has a 1-second latency, adding more bandwidth will not make a single request faster, though it will allow more requests to be processed in parallel.

    The User Experience Impact

    For web applications, latency is often the more critical metric because users perceive small delays directly. Studies have shown that even a 100-millisecond increase in page load time can reduce conversion rates. Bandwidth matters when transferring large payloads, but most API responses are relatively small JSON documents. Optimizing latency usually delivers a more noticeable improvement in perceived performance. Techniques such as keep-alive connections, HTTP/2 multiplexing, and edge caching all target latency. Meanwhile, bandwidth optimization focuses on compression, minification, and image resizing. A well-rounded performance strategy addresses both.

    Encryption: Security Without Sacrificing Speed

    Encryption is essential for protecting data in transit. Without it, sensitive information such as passwords, payment details, and personal messages can be intercepted by attackers. However, encryption has historically added latency and computational overhead. The good news is that modern encryption protocols and hardware acceleration have made the cost almost negligible for most applications. The key is understanding where the overhead comes from and how to minimize it.

    The TLS Handshake Overhead

    Transport Layer Security, or TLS, is the protocol that encrypts web traffic. When a client connects to a server over HTTPS, the two parties must first perform a handshake to agree on encryption algorithms and exchange keys. This handshake adds at least one or two network round trips before any application data is sent. For a user on a fast connection, this might add only a few dozen milliseconds. For a user on a mobile network or across a long distance, the handshake can add several hundred milliseconds. The original TLS 1.2 handshake often required two round trips. TLS 1.3 reduced this to one round trip, and when combined with session resumption, subsequent connections can be established with zero additional round trips.

    Reducing Encryption Overhead

    There are several ways to minimize the performance impact of encryption:

    • Use TLS 1.3: It reduces handshake latency and removes obsolete cryptographic algorithms.
    • Enable session resumption: This allows returning clients to skip parts of the handshake, significantly reducing latency.
    • Implement OCSP stapling: It reduces certificate revocation checks, speeding up the connection.
    • Use hardware acceleration: Modern CPUs have AES-NI and other instructions that make encryption and decryption extremely fast.
    • Terminate TLS at a load balancer or reverse proxy: This offloads cryptographic work from application servers.

    Encryption should never be treated as an optional feature that can be disabled for performance. The risks of unencrypted traffic far outweigh the small latency cost. Moreover, search engines and browsers increasingly flag non-HTTPS sites as insecure, which can harm trust and SEO. The modern approach is to enable encryption everywhere, even for internal service-to-service communication, using mutual TLS or service mesh technologies.

    API Design: The Bridge Between Systems

    An API, or Application Programming Interface, is the contract that allows different software systems to communicate. In web development, APIs are usually HTTP-based services that return JSON or XML data. A well-designed API is essential for performance, maintainability, and scalability. Poor API design leads to over-fetching, under-fetching, too many round trips, and unnecessary database load.

    Choosing the Right API Architecture

    There are several popular API architectures, each with trade-offs:

    • REST: Representational State Transfer is the most common style. It uses standard HTTP methods and resources. REST is simple, cacheable, and widely understood, but it can suffer from over-fetching and under-fetching when clients need data from multiple related resources.
    • GraphQL: A query language that lets clients request exactly the data they need in a single request. GraphQL reduces round trips and over-fetching but can introduce complex server-side query resolution and caching challenges.
    • gRPC: A high-performance framework based on HTTP/2 and protocol buffers. gRPC is excellent for internal microservices because it supports streaming, binary serialization, and strong typing, but it is less browser-friendly than REST or GraphQL.
    • WebSockets: A protocol for full-duplex communication, ideal for real-time applications such as chat, notifications, and live dashboards. WebSockets reduce the overhead of repeated HTTP requests but require different scaling strategies.

    The right choice depends on your clients, your data model, and your performance goals. Many organizations use a hybrid approach: REST or GraphQL for public APIs, gRPC for internal service-to-service calls, and WebSockets for real-time features.

    Optimizing API Latency and Bandwidth

    API performance is directly tied to latency and bandwidth. A slow API can make an otherwise fast frontend feel sluggish. Here are some proven strategies:

    • Enable HTTP caching headers: Use ETags, Cache-Control, and Last-Modified to reduce repeated requests.
    • Compress responses: Gzip or Brotli compression can reduce bandwidth usage by 60–80% for text-based data.
    • Paginate large collections: Never return thousands of records in a single response. Use limit and offset or cursor-based pagination.
    • Use field filtering: Allow clients to request only the fields they need via query parameters or GraphQL selections.
    • Implement rate limiting: Protect your API from abuse and ensure fair resource allocation.
    • Monitor and trace: Use tools like OpenTelemetry, Prometheus, and Jaeger to find slow endpoints and bottlenecks.

    API design is not just about performance. It is also about developer experience. A consistent, well-documented API with predictable error messages and clear versioning makes it easier for other teams to integrate with your service. OpenAPI, AsyncAPI, and JSON Schema are open source specifications that help standardize API contracts and generate documentation, client libraries, and server stubs automatically.

    The Power of Open Source in Modern Infrastructure

    Open source software has become the foundation of modern web infrastructure. The majority of the internet runs on open source technologies, from the Linux kernel to NGINX, Redis, PostgreSQL, Kubernetes, and countless others. Open source tools give developers the ability to inspect code, customize behavior, and avoid vendor lock-in. They also benefit from large communities that fix bugs, add features, and share knowledge.

    Core Open Source Components for Performance and Scale

    Many of the most important performance and scalability tools are open source:

    • NGINX and Apache: High-performance web servers and reverse proxies that handle TLS termination, load balancing, caching, and static file serving.
    • HAProxy: A reliable load balancer and proxy for TCP and HTTP applications.
    • Redis and Memcached: In-memory data stores used for caching, session storage, rate limiting, and message queues.
    • PostgreSQL and MySQL: Robust relational databases that power most applications.
    • Kafka and RabbitMQ: Message brokers for asynchronous processing and event-driven architectures.
    • Kubernetes: An open source container orchestration platform that automates deployment, scaling, and management of containerized applications.
    • Envoy and Istio: Service mesh technologies that provide advanced traffic management, observability, and security for microservices.

    Using open source tools does not mean everything is free. You still need to pay for infrastructure, engineering time, and possibly commercial support. However, open source provides a level of transparency and flexibility that proprietary software rarely matches. You can audit the code for security vulnerabilities, contribute patches back to the community, and run the software anywhere, from a laptop to a multi-cloud Kubernetes cluster.

    Open Source and Security

    Some people worry that open source software is less secure because attackers can read the code. In reality, open source often improves security because many eyes can find and fix vulnerabilities quickly. Projects like OpenSSL, the widely used encryption library, have been heavily audited after high-profile bugs like Heartbleed. That incident led to major improvements in funding and code review for critical open source infrastructure. For encryption specifically, open source libraries such as OpenSSL, BoringSSL, and libsodium are trusted by billions of users. Open source also enables compliance and auditability, which is essential for industries like finance and healthcare.

    Scalability: Planning for Growth

    Scalability is the ability of a system to handle increasing load without degrading performance. A scalable system can grow horizontally by adding more machines, vertically by upgrading existing hardware, or ideally both. Scalability is not just about handling millions of users on launch day. It is about maintaining predictable latency, managing bandwidth efficiently, and avoiding bottlenecks as traffic grows.

    Vertical vs Horizontal Scaling

    Vertical scaling, also called scaling up, means upgrading a single server with more CPU, memory, or faster storage. It is simple and works well for many applications, but it has physical and economic limits. Eventually, you cannot buy a bigger machine. Horizontal scaling, or scaling out, means adding more servers and distributing traffic among them. This is the preferred approach for large web applications because it provides redundancy and nearly unlimited capacity. However, horizontal scaling introduces complexity in session management, database consistency, and deployment.

    • Vertical scaling is easier: No code changes required, but it creates a single point of failure.
    • Horizontal scaling is more resilient: If one server fails, others can take over, but it requires load balancing and shared state management.
    • Stateless services scale best: Store sessions in Redis or external databases, not in local server memory.

    Scaling the Data Layer

    The application layer can be scaled relatively easily by adding more stateless API servers behind a load balancer. The database layer is usually the hardest to scale. Common techniques include:

    • Read replicas: Route read queries to replicas to reduce load on the primary database.
    • Sharding: Split data across multiple databases based on a shard key such as user ID or tenant ID.
    • Caching: Use Redis or Memcached to serve frequently accessed data without hitting the database.
    • Database connection pooling: Reuse database connections to avoid the overhead of establishing new ones for each request.
    • Asynchronous processing: Move heavy operations like email sending, image processing, and report generation to background workers using a message broker.

    Scaling for Latency and Bandwidth

    Scalability is not just about handling more requests per second. It is also about maintaining low latency and efficient bandwidth usage as the system grows. A global user base means users are far from your servers, increasing latency. A content delivery network (CDN) solves this by caching static assets and even dynamic content at edge locations close to users. Edge computing, API gateways, and distributed databases all contribute to reducing latency at scale. For bandwidth, efficient API design, compression, and payload minimization become even more important when traffic grows. A small inefficiency that costs a few kilobytes per request can turn into terabytes of wasted bandwidth at scale.

    Tying It All Together: A Blueprint for Modern Web Infrastructure

    To build a system that balances latency, bandwidth, encryption, API design, open source, and scalability, you need a holistic approach. Start by choosing open source building blocks that are proven at scale: NGINX or Envoy for edge proxying, Let’s Encrypt or cert-manager for automated TLS certificates, Redis for caching, PostgreSQL for durable storage, and Kubernetes for orchestration. Design your APIs with developer experience and performance in mind. Use REST or GraphQL for public interfaces, gRPC for internal services, and WebSockets for real-time updates. Enable TLS 1.3 everywhere, compress responses, and implement caching at multiple layers, from the CDN to the database.

    Measure everything. Use synthetic monitoring to test latency from different geographic regions. Track bandwidth usage per endpoint and per user. Profile your API responses to find slow database queries and unnecessary serialization. Use distributed tracing to understand how a single request flows through your services. Scalability is not something you add at the end. It is a property of the architecture itself. Stateless services, asynchronous processing, and decoupled components make horizontal scaling easier. Avoid tight coupling between services, and design for failure from the beginning.

    Security must be integrated into every layer. Encryption in transit is non-negotiable, but you should also encrypt sensitive data at rest, use strong authentication and authorization, and follow open source security best practices. Regularly update dependencies, scan container images for vulnerabilities, and monitor for suspicious activity. The open source community provides excellent tools for this, such as Trivy, Falco, and OPA. Remember that performance and security are not enemies. Modern encryption is fast enough for almost every use case, and many security controls actually improve reliability by preventing abuse and cascading failures.

    Conclusion

    Latency, bandwidth, encryption, APIs, open source, and scalability are deeply interconnected. A low-latency API with poor encryption may be fast but insecure. A highly secure system with poor scalability may fail under load. A scalable architecture that ignores bandwidth efficiency may become prohibitively expensive. The goal is not to maximize any single metric in isolation but to find the right balance for your specific use case. By understanding the fundamentals of network performance, embracing modern encryption protocols, designing thoughtful APIs, leveraging open source tools, and planning for horizontal growth, you can build web infrastructure that is fast, secure, and ready to scale. Technology will continue to evolve, but these principles remain the foundation of reliable, high-performance systems.

  • How to Recover a Hacked Social Media Account: A Step-by-Step Survival Guide

    How to Recover a Hacked Social Media Account: A Step-by-Step Survival Guide

    Few digital experiences are as alarming as realizing your social media account has been hijacked. One moment you are scrolling through your feed, and the next you are locked out, receiving strange messages from friends, or seeing posts you never made. A hacked account can damage your reputation, expose private conversations, and even be used to scam the people who trust you. The good news is that recovery is possible in most cases if you move quickly, follow the right steps, and remain patient. This guide will walk you through exactly how to recover a hacked social media account, secure your digital identity, and prevent future attacks.

    Over the past decade of writing about online security, I have seen the same pattern repeat itself. Hackers rely on panic, confusion, and delay. They count on you not knowing where to start or being too embarrassed to ask for help. The reality is that social media platforms have dedicated recovery systems, and they are far more effective when you use them correctly. Whether your account was compromised through a phishing link, a weak password, a data breach, or a malicious app, the recovery process follows a similar path. This article will break that process down into clear, actionable steps.

    Before we begin, remember that you are not alone. Millions of accounts are compromised every year, and the platforms themselves have seen it all. By understanding the signs of a hack, acting quickly, and using official recovery tools, you can regain control and rebuild your security. Let’s get started.

    Recognize the Signs of a Hack

    The first step in recovery is recognizing that something is wrong. Many people miss the early warning signs because they are busy or assume a glitch is to blame. However, early detection can be the difference between a quick recovery and a long, painful process. If you notice any of the following signs, treat them seriously and begin the recovery process immediately.

    • Unexpected password reset emails: You receive emails asking you to reset your password even though you did not request them.
    • Login alerts from unknown devices: The platform notifies you of a login from a city, country, or device you do not recognize.
    • Friends report strange messages: People in your network tell you they received weird links, requests for money, or unusual direct messages from your account.
    • Posts you did not create: Your timeline or story shows content you never wrote, shared, or approved.
    • Changed account details: Your profile picture, bio, username, or email address has been altered without your knowledge.
    • You are locked out: Your usual password no longer works, and the recovery email or phone number has been changed.

    If any of these apply to you, do not waste time trying to figure out how it happened. Start the recovery process now. The longer a hacker has control, the more damage they can do.

    Stay Calm and Act Fast

    It is completely natural to feel panic when you realize your account has been hacked. Your mind might race with worst-case scenarios. But panic leads to rushed decisions, and rushed decisions can make things worse. Take a deep breath. You can recover your account, but you need to act quickly and methodically. The first few hours are critical because many hackers will immediately try to lock you out further, change your recovery options, and use your account to target others.

    Start by documenting everything. Take screenshots of suspicious posts, messages, and emails. Note the time you first noticed the issue and any actions you have taken. This documentation will be useful if you need to prove your identity to the platform later. Then, move through the following steps in order. Each step builds on the previous one, and skipping ahead can reduce your chances of a smooth recovery.

    Step 1: Secure Your Email Account First

    Your email account is the master key to your digital life. If a hacker has access to your email, they can reset passwords for nearly every service you use, including social media. Before you try to recover your social media account, make sure your email account is secure. Otherwise, the hacker can simply intercept your recovery attempts and lock you out again.

    Log in to your email account from a trusted device. Change the password immediately, and make it long, unique, and complex. If your email provider offers two-factor authentication, enable it right away. Then, check the email settings for any changes the hacker may have made. Look for forwarding rules that send your messages to an unknown address, unfamiliar recovery email addresses, or new filters that hide security alerts. Remove anything you do not recognize. Finally, check the recent login activity and sign out all other sessions. This will kick the hacker out of your email and give you a secure base to work from.

    Why Email Security Comes Before Social Media

    Recovery emails, verification codes, and security alerts all go to your email inbox. If the hacker controls that inbox, they can see every step you take. By securing your email first, you cut off their access to the most important tool they have. You also create a safe channel through which the social media platform can communicate with you during the recovery process. Do not skip this step, no matter how eager you are to get your social media account back.

    Step 2: Attempt Standard Account Recovery

    Once your email is secure, go to the login page of the hacked social media platform. Do not use any links from suspicious emails. Instead, type the platform’s URL directly into your browser or use the official app. Click on the “Forgot password” or “Trouble logging in” link. This will start the official account recovery flow.

    The platform will usually ask you to provide your email address, phone number, or username. Enter the information associated with your account. If the hacker has changed these details, you may need to use the “Try another way” or “I don’t have access to these” option. Most major platforms have multiple recovery methods, including trusted contacts, previous passwords, and identity verification through a government ID.

    Follow the prompts carefully. If you are asked to enter a code sent to your email or phone, make sure you are checking the correct inbox and that your email is still secure. If the hacker changed your recovery email, you may need to use the platform’s account recovery form. This form often asks for details like the email address you used to create the account, the approximate date you created it, and a description of your recent activity. Be as accurate as possible, even if you do not know every answer.

    Using Official Recovery Forms

    When standard password reset does not work, the next step is to use the platform’s dedicated account recovery or hacked account form. These forms are designed for situations where you have lost access to your email, phone, or password. You may be asked to provide a new email address that is not currently associated with any account. This new email will be used to contact you once your identity is verified. Be patient, as this process can take anywhere from a few hours to several days depending on the platform and the volume of requests.

    Step 3: Use Trusted Devices and Locations

    Social media platforms pay close attention to the device and location you use during recovery. If you attempt to log in from a new device or an unfamiliar IP address, the platform may flag your recovery attempt as suspicious. Whenever possible, use the same phone, tablet, or computer you have used in the past to access the account. Also, try to connect from a familiar network, such as your home Wi-Fi, rather than public Wi-Fi or a VPN that changes your apparent location.

    Using a trusted device and location signals to the platform that you are the legitimate account owner. It can also unlock additional recovery options that are not available on unknown devices. If you must use a different device, be prepared to answer more security questions or provide additional proof of identity. The goal is to make it as easy as possible for the platform to confirm that you are the real owner of the account.

    Step 4: Report the Hack to the Platform

    If you cannot recover your account through the standard flow, you should formally report the hack. Most platforms have a specific option for reporting a compromised account. This option is often found in the help center or through a special URL. For Facebook, you can use the “Report Compromised Account” page. For Instagram, there is a “Need more help?” link on the login screen. For X (formerly Twitter), you can use the “Account Access” support form. For TikTok, LinkedIn, and others, look for “hacked account” in the help center.

    When you report the hack, be clear and concise. Provide all the information requested, including the email address and phone number associated with the account, a description of what happened, and any screenshots you have. Avoid emotional language or vague claims. The support team needs facts, not frustration. If you have followed the previous steps, you will be able to show that you have already secured your email and attempted standard recovery. This can speed up the review process.

    • Facebook: Visit the Help Center and use the “Report Compromised Account” tool to secure your account and change your password.
    • Instagram: Tap “Get help logging in” on the login screen and follow the prompts for a hacked account.
    • X (Twitter): Use the “Account Access” form and select “I have been hacked” as the issue.
    • TikTok: Go to the app or website and select “Account Recovery” from the support options.
    • LinkedIn: Use the “Report a compromised account” page in the Help Center.

    Step 5: Alert Your Contacts Immediately

    While you are waiting for the platform to respond, you need to warn the people who might be targeted by the hacker. Hackers often use compromised accounts to send phishing links, ask for money, or spread scams. Your friends and family are more likely to trust a message that comes from your account, even if it seems unusual. If you wait too long, someone you care about could fall for the scam.

    Choose another communication method to reach your contacts. You can send a group text, make phone calls, or post from a different social media account. Let people know that your account was hacked and that they should ignore any suspicious messages or links they may have received from you. Tell them not to send money, click links, or share personal information in response to requests from your account. This simple step can prevent a lot of damage and protect your reputation.

    Step 6: Check Connected Apps and Sessions

    Once you regain access to your account, do not assume the threat is over. Hackers often leave behind connected apps, active sessions, or new recovery methods that allow them to regain access later. You need to conduct a thorough security audit before you resume normal use.

    Go to your account settings and look for the security or privacy section. Find the area that shows active sessions or logged-in devices. Review each session and sign out of any that you do not recognize. If you see a login from a city or device you have never used, remove it immediately. Then, check the connected apps and websites section. Revoke access to any app you do not remember installing or that looks suspicious. Hackers sometimes use third-party apps to maintain access even after you change your password.

    Audit Your Account Details

    While you are in the settings, verify that your email address, phone number, username, and profile information are correct. Hackers often change these details to make it harder for you to recover the account later. If anything is wrong, change it back and save the new information. Also, check your bio, posts, and direct messages for anything the hacker may have left behind. Delete any unauthorized content and apologize to anyone who may have been affected.

    Step 7: Restore and Strengthen Security

    With your account back in your control, it is time to build a stronger defense. The first step is to create a new, strong password. Do not reuse a password you have used before, and do not use a variation of your old password. A strong password should be at least 12 characters long and include a mix of uppercase letters, lowercase letters, numbers, and symbols. Better yet, use a passphrase made of random words. The goal is to make it impossible for a hacker to guess or crack.

    Create a Strong Password

    Use a password manager to generate and store unique passwords for every account. Password managers create long, random strings that are far more secure than anything you could remember. They also fill in passwords automatically, which reduces the temptation to reuse passwords across sites. If you do not already use a password manager, now is the time to start. Choose one with a strong reputation and enable its own two-factor authentication.

    Enable Two-Factor Authentication

    Two-factor authentication, or 2FA, is the single most effective way to protect your social media accounts. With 2FA enabled, a hacker cannot log in even if they have your password. They would also need a code from your phone, an authenticator app, or a security key. Every major social media platform supports 2FA, and you should enable it on all of your accounts immediately.

    Choose an authenticator app over SMS-based 2FA if possible. Authenticator apps generate codes that are not tied to your phone number, which makes them more resistant to SIM-swapping attacks. If you cannot use an authenticator app, SMS is still better than nothing. Write down the backup codes the platform provides and store them in a safe place. These codes will let you get back into your account if you lose access to your phone.

    • Use a password manager: Generate and store unique passwords for every account.
    • Enable 2FA everywhere: Prioritize authenticator apps over SMS.
    • Save backup codes: Store them offline in a secure location.
    • Remove unknown apps and sessions: Regularly audit your account security settings.
    • Be suspicious of links: Never click on a link in an unexpected email or message, even if it looks legitimate.

    Preventing Future Hacks

    Recovering a hacked account is only half the battle. The other half is preventing it from happening again. Most hacks are not the result of a sophisticated cyberattack. They are the result of common mistakes like reusing passwords, falling for phishing, or ignoring security warnings. By changing a few habits, you can dramatically reduce your risk.

    First, never reuse passwords across accounts. If one account is breached, every account that shares that password becomes vulnerable. A password manager makes this easy by creating a unique password for each site. Second, be wary of any message that asks you to click a link and log in. Phishing is one of the most common ways hackers steal credentials. Always check the URL before entering your password. When in doubt, go directly to the platform’s website or app instead of clicking a link. Third, keep your email account secure. Since email is the recovery method for most services, a compromised email account can lead to a cascade of hacks. Use a strong password and 2FA on your email, and review its security settings regularly.

    Finally, stay informed about the latest scams. Hackers are constantly changing their tactics, and what seemed safe a year ago may be risky today. Follow reputable security blogs, pay attention to platform security announcements, and talk to your friends and family about what you learn. The more you know, the harder it is for hackers to catch you off guard.

    What If You Cannot Recover the Account?

    Sometimes, despite your best efforts, a hacked account cannot be recovered. This can happen if the hacker successfully changed all of your recovery information and the platform’s review process does not accept your proof of identity. It can also happen if the account was permanently deleted or banned because of the hacker’s actions. If you find yourself in this situation, do not give up hope. You still have options.

    First, continue working with the platform’s support team. Escalate your case if possible, and provide any additional documentation they request. Sometimes persistence pays off, and a case that was initially rejected can be reopened. Second, notify your contacts again and encourage them to report your old account as hacked. If enough people report it, the platform may take action and disable the compromised account. Third, if you have lost access to an account that is important for your business or personal brand, consider creating a new account. Secure it properly from the start, and reach out to your audience to let them know what happened. It is a setback, but it does not have to be the end of your online presence.

    Conclusion

    Learning how to recover a hacked social media account is an essential skill in today’s connected world. A compromised account can feel like a personal violation, but it is a problem with clear solutions. By recognizing the signs of a hack, acting quickly, securing your email, using official recovery tools, and alerting your contacts, you can regain control and limit the damage. Once you are back in, take the time to strengthen your security with a strong password, two-factor authentication, and regular security audits.

    Remember that prevention is always better than recovery. The habits you build today—using a password manager, enabling 2FA, questioning suspicious links, and keeping your email secure—will protect you for years to come. Social media is a powerful tool for connection and expression, and with the right precautions, you can enjoy it without becoming an easy target. If the worst happens, stay calm, follow the steps in this guide, and know that you have the power to take back control.

  • Best Free Alternatives to Adobe Photoshop in 2025: Edit Like a Pro Without Paying a Penny

    Best Free Alternatives to Adobe Photoshop in 2025: Edit Like a Pro Without Paying a Penny

    Best Free Alternatives to Adobe Photoshop in 2025: Edit Like a Pro Without Paying a Penny

    For years, Adobe Photoshop has been the undisputed industry standard for photo editing, graphic design, and digital art. But with a subscription that can easily cost more than $20 per month, Photoshop is not a realistic option for every blogger, freelancer, student, or hobbyist. The good news is that the landscape of free image editing software has grown dramatically. Today, there are several powerful programs that can handle layers, masks, retouching, RAW files, and even PSD documents without charging a single cent. In this guide, we will explore the best free alternatives to Adobe Photoshop in 2025, explain what makes each one unique, and help you decide which tool fits your creative workflow best.

    Whether you need to remove a background from a product photo, create social media graphics, restore an old family picture, or paint concept art, there is a free tool that can get the job done. Some of these applications are browser-based, meaning you can use them on any device with an internet connection. Others are open-source desktop programs that offer deep customization and plugin support. By understanding the strengths and limitations of each option, you can save money without sacrificing quality or creative control.

    Why You Don’t Need to Pay for Photoshop Anymore

    There was a time when choosing a free image editor meant accepting a frustratingly basic program with no layers, poor selection tools, and limited file format support. That era is over. Modern free editors have matured into capable applications that can handle professional tasks. Tools like GIMP and Photopea now include advanced features such as non-destructive editing, layer masks, blending modes, smart objects, and even PSD file support. This means you can open and edit Photoshop files without owning Photoshop, collaborate with others, and produce high-resolution work for print or web.

    Another reason to consider a free alternative is performance. Photoshop is a resource-intensive program that requires a fairly powerful computer, especially when working with large files or multiple layers. Many free editors are lighter and faster, making them ideal for older laptops, low-end desktops, or users who simply want a quick edit without waiting for a heavy program to load. Browser-based tools take this further by eliminating installation entirely, allowing you to edit photos on a Chromebook, a public computer, or even a tablet.

    Cost is obviously a major factor. A single Adobe subscription may seem manageable, but over time it adds up. Freelancers and small business owners can redirect that money toward other tools, marketing, or equipment. Open-source communities have also made incredible progress in usability and documentation, so the learning curve is no longer as intimidating as it once was. With a bit of practice, you can achieve results that rival Photoshop on a budget of zero dollars.

    What to Look for in a Free Photo Editor

    Before diving into the list of the best free alternatives to Adobe Photoshop, it helps to know which features matter most. Not every editor is designed for the same purpose, and the right choice depends on your specific tasks. Here are the key capabilities to evaluate:

    • Layer support: Layers are essential for non-destructive editing, compositing multiple images, and applying adjustments without permanently altering pixels.
    • Selection tools: Advanced selection tools such as the lasso, magic wand, quick selection, and pen tool are critical for isolating subjects and making precise edits.
    • Retouching tools: Healing brushes, clone stamps, and content-aware fill features help remove blemishes, distractions, or unwanted objects from photos.
    • File format compatibility: If you work with clients or collaborators, PSD support is important. Many free editors can open PSD files, though some may not support every Photoshop feature.
    • RAW file editing: Photographers need a tool that can process RAW files from cameras. Some free editors include RAW support natively, while others require a plugin or companion application.
    • Adjustment layers and filters: Non-destructive adjustment layers let you fine-tune brightness, contrast, color balance, and curves without losing original image data.
    • Platform and performance: Consider whether you need Windows, macOS, Linux, or browser-based access. Also check whether the editor runs smoothly on your hardware.
    • Learning curve: Some free editors closely mimic Photoshop’s layout, while others have their own unique interface. Choose one that matches your patience and experience level.

    The Best Free Alternatives to Adobe Photoshop in 2025

    Below are the most powerful and widely used free image editors available today. Each one has a distinct personality, so you may find that a combination of tools works best for your needs.

    GIMP (GNU Image Manipulation Program)

    GIMP is widely considered the most direct free alternative to Photoshop. It is an open-source desktop application that has been in development for decades, and it runs on Windows, macOS, and Linux. GIMP offers a comprehensive feature set that includes layers, layer masks, advanced selection tools, bezier paths, customizable brushes, and a huge collection of filters and plugins. It also supports pressure-sensitive graphics tablets, making it suitable for both photo editing and digital painting.

    One of GIMP’s biggest strengths is its flexibility. You can customize nearly every part of the interface, create your own keyboard shortcuts, and install community-made plugins to extend functionality. GIMP can open and save PSD files, which makes it possible to collaborate with Photoshop users, although some advanced Photoshop features may not translate perfectly. The main drawback is the learning curve. GIMP’s interface can feel overwhelming at first, and some users find it less polished than Photoshop. However, if you are willing to invest time in learning the tool, it is capable of professional-grade results.

    • Best for: Advanced photo manipulation, graphic design, and users who prefer open-source software.
    • Platforms: Windows, macOS, Linux.
    • Key features: Layers, masks, paths, customizable brushes, plugin support, PSD compatibility.
    • Limitations: Steeper learning curve, no native RAW editing without plugins, and occasional performance issues with very large files.

    Krita

    Krita is another open-source powerhouse, but it is best known as a digital painting and illustration program rather than a photo editor. That said, it contains many tools that photo editors need, including layers, masks, non-destructive adjustment layers, transform tools, healing brushes, smart patch tools, and a wide range of filters. Krita’s brush engine is among the best in any free software, and it is a favorite among concept artists, comic creators, and illustrators.

    For users who want to combine photo editing with artistic painting, Krita is an excellent choice. You can retouch a photo, then paint over it with custom brushes, add textures, or create completely original artwork. It supports PSD files to a limited degree, but its focus is not on Photoshop compatibility. RAW editing is not a primary feature, so photographers may need a separate RAW processor. Still, for creative projects and illustration-heavy workflows, Krita is a top-tier free option.

    • Best for: Digital painting, illustration, concept art, and hybrid photo-art projects.
    • Platforms: Windows, macOS, Linux.
    • Key features: Outstanding brush engine, layers, masks, animation tools, non-destructive adjustment layers.
    • Limitations: Less intuitive for traditional photo editing, limited PSD support, no native RAW processing.

    Photopea

    Photopea is a browser-based editor that looks and feels remarkably similar to Adobe Photoshop. It is free to use with ads, and a premium subscription removes ads while supporting the developer. Photopea supports an impressive range of file formats, including PSD, XCF, Sketch, PDF, and RAW files. It offers layers, masks, blending modes, adjustment layers, layer styles, smart objects, and even some advanced Photoshop features that many desktop alternatives lack.

    The biggest advantage of Photopea is accessibility. Since it runs in any modern web browser, you can use it on Windows, macOS, Linux, Chromebook, or even a tablet. There is nothing to install, and your work can be saved to your device or cloud storage. For anyone who needs to open a PSD file quickly or make a Photoshop-style edit on a computer they don’t own, Photopea is invaluable. Its performance may slow down with very large files or complex documents, but for most everyday tasks it is impressively fast and capable.

    • Best for: Users who want a Photoshop-like experience without installing software, and anyone who needs to open or edit PSD files quickly.
    • Platforms: Any device with a modern web browser.
    • Key features: PSD support, layers, masks, adjustment layers, smart objects, layer styles, RAW support.
    • Limitations: Requires internet connection for best performance, ad-supported free version, can struggle with extremely large files.

    Paint.NET

    Paint.NET began as a simple replacement for Microsoft Paint, but it has grown into a capable layer-based image editor. It is only available for Windows, which may be a drawback for Mac and Linux users, but its lightweight design and ease of use make it a favorite among Windows users who want fast results without a steep learning curve. Paint.NET supports layers, unlimited undo, blend modes, adjustments, effects, and a thriving plugin ecosystem.

    While Paint.NET does not offer the same depth as GIMP or Photoshop, it is perfect for quick photo fixes, screenshot annotation, simple graphic design, and users who are new to image editing. Its interface is clean and approachable, and the program runs quickly even on older computers. For more advanced work, you may need to install plugins or switch to another tool, but Paint.NET remains one of the easiest desktop editors to learn.

    • Best for: Beginners, Windows users, and anyone who needs a fast, simple editor for everyday tasks.
    • Platforms: Windows only.
    • Key features: Layers, unlimited undo, blend modes, adjustments, effects, plugin support.
    • Limitations: No native PSD or RAW support, fewer advanced features than GIMP or Photopea, Windows-only.

    Pixlr X and Pixlr E

    Pixlr offers two browser-based editors: Pixlr X for quick, template-driven design and Pixlr E for more advanced, layer-based editing. Both are free with ads, and they run in any web browser. Pixlr E supports layers, masks, basic retouching tools, filters, overlays, and text. Pixlr X focuses on ease of use with one-click effects, AI background removal, and social media templates. This makes Pixlr a great option for social media managers, content creators, and users who need to produce polished images quickly.

    Pixlr is not as deep as Photopea or GIMP, and some of its more advanced AI features are locked behind a premium plan. However, for basic editing and fast online work, it is one of the most user-friendly tools available. The interface is colorful and modern, making it less intimidating for beginners. If you need to create a quick Instagram post, remove a background, or add text to a photo, Pixlr can handle the job in minutes.

    • Best for: Social media graphics, quick edits, and beginners who prefer a browser-based tool.
    • Platforms: Any device with a modern web browser.
    • Key features: Layers, masks, AI background removal, templates, filters, overlays.
    • Limitations: Fewer advanced photo manipulation features, ads in free version, some AI tools require premium.

    Canva

    Canva is not a traditional pixel-based photo editor, but it deserves a place in any discussion of the best free alternatives to Adobe Photoshop because many people who think they need Photoshop actually need a design tool. Canva’s free plan offers drag-and-drop design, thousands of templates, text effects, photo filters, and basic adjustments. It is ideal for creating social media posts, blog graphics, presentations, posters, and marketing materials without any design experience.

    While Canva cannot do advanced retouching, compositing, or pixel-level manipulation, it excels at speed and simplicity. Beginners can produce professional-looking graphics in minutes, and teams can collaborate in real time. Many small business owners and bloggers use Canva as their primary design tool and pair it with a dedicated photo editor for more detailed image work. The free plan is generous, though some premium elements and features require a paid subscription.

    • Best for: Social media graphics, blog images, presentations, and simple design projects.
    • Platforms: Web-based, iOS, Android.
    • Key features: Drag-and-drop templates, text tools, photo filters, brand kits, collaboration.
    • Limitations: Not suitable for advanced photo editing, some templates and AI tools require premium.

    Darktable and RawTherapee

    If your primary need is processing RAW photos from a digital camera, then Darktable and RawTherapee are two of the best free alternatives to Adobe Lightroom and Photoshop’s Camera Raw. Darktable is an open-source RAW developer with non-destructive editing, color correction, masking, lens correction, and a powerful export system. RawTherapee excels at detail recovery, noise reduction, and precise control over image quality. Both applications run on Windows, macOS, and Linux.

    These tools are not full pixel editors like Photoshop, but they handle the crucial first stage of a photographer’s workflow. You can adjust exposure, white balance, contrast, color, sharpness, and more, then export a high-quality TIFF or JPEG for further editing in GIMP or another editor. For many photographers, pairing Darktable or RawTherapee with GIMP creates a complete, professional Photoshop replacement that costs nothing.

    • Best for: Photographers who need advanced RAW processing and non-destructive editing.
    • Platforms: Windows, macOS, Linux.
    • Key features: RAW processing, non-destructive editing, color correction, masking, batch processing.
    • Limitations: Not designed for pixel-level compositing or graphic design, steeper learning curve for beginners.

    PhotoScape X

    PhotoScape X is a free, all-in-one photo editor for Windows and macOS that focuses on simplicity and fun. It includes batch editing, a collage maker, GIF creation, screen capture, RAW support, frames, filters, and basic retouching tools. PhotoScape X is not meant for complex compositing or deep photo manipulation, but it is perfect for quick fixes, batch resizing, and creative projects like scrapbooking or social media graphics.

    The interface is friendly and accessible, making it a good option for families, teachers, and casual users who want more than basic cropping but less complexity than GIMP. A paid pro version unlocks additional features, but the free version is generous enough for most everyday tasks. If you need to edit hundreds of photos at once or create a fun collage, PhotoScape X is a time-saving tool worth having.

    • Best for: Batch editing, collages, GIFs, and quick, playful photo projects.
    • Platforms: Windows, macOS.
    • Key features: Batch editing, collage maker, GIF creation, RAW support, filters, frames.
    • Limitations: Limited advanced editing tools, some features require paid upgrade.

    How to Choose the Right Free Photoshop Alternative

    With so many strong options, the best choice depends on your specific needs and working style. If you are a photographer who shoots in RAW, start with Darktable or RawTherapee, then use GIMP for detailed retouching. If you are a digital artist, Krita is likely the most inspiring tool. If you need to open PSD files or work on many different devices, Photopea is a natural fit. For fast social media graphics, Canva and Pixlr offer speed and simplicity that Photoshop cannot match without templates and presets.

    Consider your hardware and operating system as well. Windows users can choose among Paint.NET, GIMP, Krita, PhotoScape X, and many others. Mac and Linux users have excellent open-source options in GIMP, Krita, and Darktable. Browser-based tools like Photopea and Pixlr remove the platform question entirely. Also think about whether you prefer a one-time download or a tool that lives in your browser. Some users like the feeling of a local application, while others value the flexibility of editing from any device.

    Finally, give yourself time to experiment. No two free editors behave exactly like Photoshop, even if they share similar features. Keyboard shortcuts, menu layouts, and tool names may differ. The best approach is to pick one or two tools that match your primary tasks, watch a few tutorials, and start a small project. You may find that a combination of free tools gives you everything you need without ever paying for a subscription.

    Tips for Transitioning from Photoshop to a Free Alternative

    Switching from Photoshop to a free editor can feel frustrating at first, especially if you have years of muscle memory built around Photoshop’s shortcuts and layout. The good news is that most editors allow some level of customization. Start by learning the basic workspace and identifying the tools you use most often. Then customize shortcuts and panels to create a familiar environment. Many free editors also have active communities and extensive documentation that can help you through the transition.

    • Replicate your most-used actions: Make a list of the tasks you perform daily and find their equivalents in the new editor.
    • Use plugins and extensions: GIMP and Paint.NET have large plugin libraries that add missing features.
    • Watch tutorials: YouTube and official documentation are full of beginner guides for GIMP, Krita, Photopea, and others.
    • Be patient: A new interface takes time to feel natural, but most users adapt within a few weeks.
    • Keep Photoshop files organized: If you still have PSD files, test how each editor opens them before committing to a full switch.

    Conclusion

    The best free alternatives to Adobe Photoshop in 2025 offer an impressive range of features, from advanced layer editing and PSD compatibility to RAW processing and digital painting. GIMP delivers deep, Photoshop-like control for desktop users. Photopea brings that power to the browser. Krita is a dream for digital artists, while Paint.NET and PhotoScape X provide lightweight simplicity. Pixlr and Canva make quick online design easy, and Darktable and RawTherapee cover professional photography workflows.

    You no longer have to pay a monthly subscription to edit images professionally. By choosing the right free tool or combining a few of them, you can retouch photos, design graphics, process RAW files, and create stunning digital art without spending a penny. The key is to understand your needs, experiment with the options, and invest a little time in learning. Once you do, you will discover that creative freedom does not have to come with a price tag.

  • How to Stop Apps from Tracking You on iPhone: A Complete Privacy Guide

    How to Stop Apps from Tracking You on iPhone: A Complete Privacy Guide

    Your iPhone is one of the most powerful personal devices you own, but it is also a gateway through which apps and advertisers can learn a surprising amount about you. Every tap, search, location update, and interaction can be collected, bundled, and shared in ways you may never see. The good news is that Apple has built a growing set of tools into iOS that put control back in your hands. If you have ever wondered how to stop apps from tracking you on iPhone, the answer is not a single switch—it is a combination of settings, permissions, and habits that work together to protect your privacy.

    In this guide, we will walk through every meaningful privacy setting on your iPhone, from App Tracking Transparency to Location Services, advertising identifiers, app permissions, and even Safari protections. Whether you want to stop cross-app tracking, prevent an app from knowing your precise location, or simply reduce the amount of data collected about your daily routine, this article will give you clear, step-by-step instructions and practical privacy strategies.

    By the end, you will have a much stronger privacy posture on your iPhone, and you will understand exactly where data tracking hides and how to block it. None of these steps require technical expertise. All you need is a few minutes and a willingness to open the Settings app.

    Understanding How Apps Track You on iPhone

    Before changing settings, it helps to understand what app tracking really means. On an iPhone, app tracking generally refers to the ability of apps and third-party companies to collect data about your behavior and link it to an advertising profile or share it with data brokers. This can include your location, search history, purchase habits, device information, and the other apps you use.

    Apple uses an Identifier for Advertisers, or IDFA, to allow advertisers and app developers to measure campaign performance and target ads across different apps. When an app wants to track you across apps and websites owned by other companies, it must ask for your permission through a system called App Tracking Transparency. If you deny permission, the app cannot access your IDFA, which makes cross-app tracking significantly harder.

    However, tracking is not limited to advertising identifiers. Apps can also track your physical location, scan your local network, read your clipboard, access your contacts, photos, camera, microphone, and more. They may use Bluetooth signals in stores to understand your shopping behavior, or they may request background refresh access to run in the background. A complete privacy strategy means auditing every one of these pathways.

    Master App Tracking Transparency

    App Tracking Transparency is Apple’s primary defense against cross-app tracking. Introduced in iOS 14.5, it forces apps to ask for your consent before they can track your activity across other companies’ apps and websites. You have probably seen the pop-up: “Allow [App] to track your activity across other companies’ apps and websites?” Choosing “Ask App Not to Track” is one of the most effective ways to stop app tracking on iPhone.

    How to Check Your Tracking Settings

    To manage App Tracking Transparency, follow these steps:

    • Open Settings on your iPhone.
    • Tap Privacy & Security.
    • Tap Tracking.
    • Review the list of apps that have requested permission to track you.
    • Toggle off any app you want to deny.

    Turn Off All Future Tracking Requests

    If you do not want apps to even ask for permission, you can turn off the entire system. In the same Tracking menu, toggle off Allow Apps to Request to Track. When this setting is off, apps cannot show the tracking prompt, and your IDFA is automatically shielded. This is the fastest way to stop cross-app tracking without having to deal with endless permission pop-ups.

    For most people, turning off Allow Apps to Request to Track is the single most impactful privacy change they can make. It does not break apps. You can still use all your favorite services, but they will no longer be able to track you across other companies’ platforms using Apple’s advertising identifier.

    Control Location Services with Precision

    Location data is one of the most sensitive categories of personal information. It can reveal where you live, where you work, where you worship, where you shop, and when you are away from home. Many apps request location access even when they do not truly need it. By auditing Location Services, you can stop apps from tracking your physical movements.

    Review App-by-App Location Permissions

    Go to Settings > Privacy & Security > Location Services. You will see a list of every app that has requested location access. Each app can be set to:

    • Never – The app cannot access your location at all.
    • Ask Next Time Or When I Share – The app must ask every time it wants location access.
    • While Using the App – Location is available only when the app is open and active.
    • Always – The app can access location even in the background, which is rarely necessary.

    For most apps, While Using the App or Never is the appropriate choice. Very few apps genuinely need Always access. Rideshare apps, navigation apps, and safety apps may benefit from background location, but a game, shopping app, or social network almost certainly does not.

    Disable Precise Location

    Even when you allow an app to see your location, you can hide your exact coordinates. On the location permission screen for an individual app, you will see a toggle called Precise Location. Turn it off to provide only an approximate area, usually within a few miles, instead of your exact street address. This is perfect for weather apps, news apps, or any service that only needs to know your general city.

    Limit System Services Tracking

    Location tracking is not limited to third-party apps. Apple itself collects location data through System Services. Scroll to the bottom of Location Services and tap System Services. Here you can disable options such as:

    • Significant Locations – This records places you frequently visit. You can clear the history and turn it off.
    • iPhone Analytics – Sends location-related analytics to Apple.
    • Routing & Traffic – Helps improve maps but is not essential.
    • Location-Based Apple Ads – Uses your location to serve Apple ads.
    • Popular Near Me – Shares your location with Apple to improve suggestions.

    Turning off unnecessary System Services reduces the amount of location data collected even when you are not using a specific app.

    Audit App Permissions Beyond Location

    Location is only one part of the tracking picture. Apps can also access your contacts, photos, camera, microphone, Bluetooth, local network, and more. Each of these permissions can be misused for profiling, tracking, or data collection. A thorough privacy audit should include every permission category.

    Camera, Microphone, Photos, and Contacts

    Go to Settings > Privacy & Security and review each section: Camera, Microphone, Photos, Contacts, Calendars, and Reminders. Ask yourself whether each app truly needs that access. A social media app likely needs camera and photo access to post content, but a shopping app may not need your contacts. Revoke any permission that feels excessive or unnecessary.

    Bluetooth Tracking

    Many people do not realize that Bluetooth can be used for physical tracking. Stores, airports, and venues sometimes use Bluetooth beacons to detect nearby devices. Apps can use Bluetooth to map your location indoors or trigger marketing messages. Go to Settings > Privacy & Security > Bluetooth and turn off Bluetooth access for apps that do not genuinely need it, such as retail apps, games, or random utility apps.

    Local Network Access

    Apps that request access to your local network can scan for other devices on your Wi-Fi network, such as smart TVs, speakers, and cameras. This information can reveal a lot about your home setup. Review Settings > Privacy & Security > Local Network and turn off access for apps that do not need to communicate with local devices. Most apps have no legitimate reason to scan your network.

    Motion and Fitness Data

    Your iPhone can count steps, estimate movement, and collect fitness data. Some apps use this data to provide health features, but others may use it for behavior profiling. Check Settings > Privacy & Security > Motion & Fitness and disable fitness tracking for apps that do not need it.

    Reduce Ad Tracking and Analytics

    Apple includes several advertising and analytics settings that affect how your data is used for marketing and product improvement. These settings do not stop all tracking, but they reduce the amount of data shared with Apple and its advertising partners.

    Turn Off Personalized Apple Ads

    Apple’s own advertising platform can use your data to serve personalized ads in the App Store, Apple News, and Stocks. To limit this, go to Settings > Privacy & Security > Apple Advertising and turn off Personalized Ads. You will still see ads, but they will not be tailored based on your activity.

    Disable Analytics and Improvements

    Apple collects diagnostics and usage data by default. You can reduce this by going to Settings > Privacy & Security > Analytics & Improvements and turning off:

    • Share iPhone Analytics
    • Share iCloud Analytics
    • Share iPhone & Watch Analytics
    • Improve Siri & Dictation if you do not want voice recordings shared.

    This does not directly stop third-party app tracking, but it minimizes the overall data trail tied to your device.

    Use App Privacy Labels as a Decision Tool

    Before you download a new app, check its privacy label on the App Store. Apple requires developers to disclose their data collection practices. On an app’s product page, scroll to App Privacy and tap See Details. You will see three categories: Data Used to Track You, Data Linked to You, and Data Not Linked to You.

    If an app lists extensive data in the “Data Used to Track You” section, consider whether you really need that app or whether a privacy-friendlier alternative exists. Many popular apps collect location, contact info, identifiers, and purchase history. Choosing apps with minimal tracking labels is one of the most proactive ways to stop app tracking on iPhone before it even starts.

    Review Background App Refresh

    Background App Refresh allows apps to update content in the background when you are not actively using them. This can be useful for email or messaging apps, but it also gives apps more opportunities to collect and transmit data. To limit this, go to Settings > General > Background App Refresh and turn it off entirely, or disable it for specific apps.

    Turning off Background App Refresh does not break apps. They will simply refresh when you open them. It can also save battery life and reduce mobile data usage, making it a smart privacy and performance choice.

    Secure Safari and Web Tracking

    Tracking does not only happen inside apps. Websites and web-based trackers can follow you across the internet and build a profile about your interests. Safari includes several privacy features that help stop web tracking.

    Enable Intelligent Tracking Prevention

    Go to Settings > Safari and make sure Prevent Cross-Site Tracking is turned on. This limits trackers that follow you from one website to another. You should also enable Hide IP Address from Trackers if available, which prevents websites and trackers from using your IP address to identify you.

    Block All Cookies

    Blocking all cookies can improve privacy, but it may cause some websites to break or require frequent sign-ins. For most users, keeping Prevent Cross-Site Tracking enabled is enough. If you want maximum privacy, you can turn on Block All Cookies, but be prepared for a less seamless browsing experience.

    Use Privacy Report

    Safari includes a Privacy Report that shows which trackers were blocked on the websites you visit. Tap the aA icon in Safari and select Privacy Report to see how many trackers have been prevented. This gives you a clear view of how actively websites attempt to follow you.

    Use Sign in with Apple and Hide My Email

    When you sign up for an app or service, you often provide an email address. That email can be used to track you across websites, apps, and data broker databases. Apple offers tools to reduce this risk.

    Sign in with Apple lets you authenticate with apps without sharing your personal email address. Apple can generate a random, unique email that forwards messages to your real inbox. This prevents the app from knowing your actual email and reduces cross-platform tracking. To use it, simply choose Sign in with Apple on supported apps and select Hide My Email.

    You can also use Hide My Email independently if you subscribe to iCloud+. Go to Settings > Your Name > iCloud > Hide My Email to create unique forwarding addresses for any website or service. This is an excellent way to keep your real email address private.

    Consider iCloud Private Relay for Safari Traffic

    If you have an iCloud+ subscription, you can enable Private Relay, which encrypts Safari traffic and routes it through two separate relays so that no single entity can see both your IP address and your browsing activity. Private Relay is designed to protect web browsing in Safari, not all app traffic, but it adds another layer of privacy when browsing.

    To enable Private Relay, go to Settings > Your Name > iCloud > Private Relay and turn it on. You can also choose to hide your IP address from trackers and websites in Safari settings. Private Relay is not a full VPN, but it significantly reduces the ability of websites and network providers to build a profile based on your IP address.

    Reset Your Advertising Identifier

    Even with App Tracking Transparency enabled, you can reset your advertising identifier to disrupt any existing ad profile tied to your device. To do this, go to Settings > Privacy & Security > Tracking. If you have previously allowed tracking, you can disable it for individual apps. Additionally, under Settings > Privacy & Security > Apple Advertising, you can turn off personalized ads. Resetting the identifier is less prominent on modern iOS versions, but maintaining a tight tracking permission list achieves the same goal.

    Delete Unused or High-Tracking Apps

    The most effective way to stop an app from tracking you is to delete it. If you have apps that you rarely use, or that have a poor privacy label, consider removing them. Many services can be accessed through a mobile browser instead of a dedicated app, often with fewer tracking permissions.

    Regularly audit your home screen. For each app, ask whether the value it provides is worth the data it collects. You may find that you can replace several apps with privacy-respecting alternatives, or simply do without them. This reduces your overall digital footprint and limits the number of companies that can follow your behavior.

    Use Content Blockers and Privacy-Focused Browsers

    In addition to Safari’s built-in protections, you can install content blockers from the App Store. These blockers use rule lists to prevent third-party trackers, social media widgets, and invasive ads from loading. Popular privacy-focused browsers, such as Firefox Focus, Brave, or DuckDuckGo, also include strong anti-tracking features by default.

    If you primarily browse the web through a dedicated browser, using one with strong privacy defaults can dramatically reduce web-based tracking. For in-app browsing, Safari settings still apply, so keep Prevent Cross-Site Tracking enabled and consider blocking cookies if you are willing to accept some usability trade-offs.

    Monitor App Permissions Over Time

    Privacy is not a set-and-forget task. Apps update frequently, and new features may request additional permissions. Make it a habit to review your privacy settings every few weeks. Check the Tracking menu, Location Services, and other permission categories to see if any app has been granted more access than you intended.

    iOS also provides privacy indicators. A small orange dot appears when an app uses the microphone, and a green dot appears when an app uses the camera. If you see these dots when you do not expect them, go to Settings > Privacy & Security and investigate which app was responsible. This can alert you to potential misuse and help you stop tracking before it becomes a larger problem.

    What to Do If an App Still Tracks You

    There is no perfect way to eliminate all tracking, because some data collection is intrinsic to how apps operate. However, if you believe an app is tracking you despite your settings, you can take several steps. First, revoke all unnecessary permissions for that app. Second, turn off Background App Refresh. Third, reset its permission by deleting and reinstalling the app, then denying every prompt. Finally, if the app continues to collect excessive data, report it through the App Store or delete it entirely.

    You should also be aware that some tracking happens through methods that do not require Apple’s permission system, such as fingerprinting based on device characteristics, IP address, and usage patterns. Using Private Relay, a VPN, or a privacy-focused browser can help reduce these forms of tracking, but the strongest defense is to limit the number of apps you use and the data you share with them.

    Conclusion

    Stopping apps from tracking you on iPhone is not about finding one magic switch. It is about building a layered privacy strategy that includes App Tracking Transparency, strict location permissions, careful app permission audits, reduced advertising and analytics data, browser protections, and ongoing vigilance. Apple gives you powerful tools, but they only work if you use them.

    Start with the most impactful step: open Settings > Privacy & Security > Tracking and turn off Allow Apps to Request to Track. Then review location access, revoke unnecessary camera, microphone, Bluetooth, and local network permissions, and disable personalized ads. Finally, make privacy a habit by checking your settings regularly and choosing apps with transparent data practices.

    Your iPhone is a personal device, and your data should be personal too. With the steps in this guide, you can dramatically reduce tracking, protect your location, obscure your identity, and take back control of your digital privacy. The apps on your phone work for you—not the other way around.